Infrastructure Audit Checklist: What I Check During a DevOps Audit
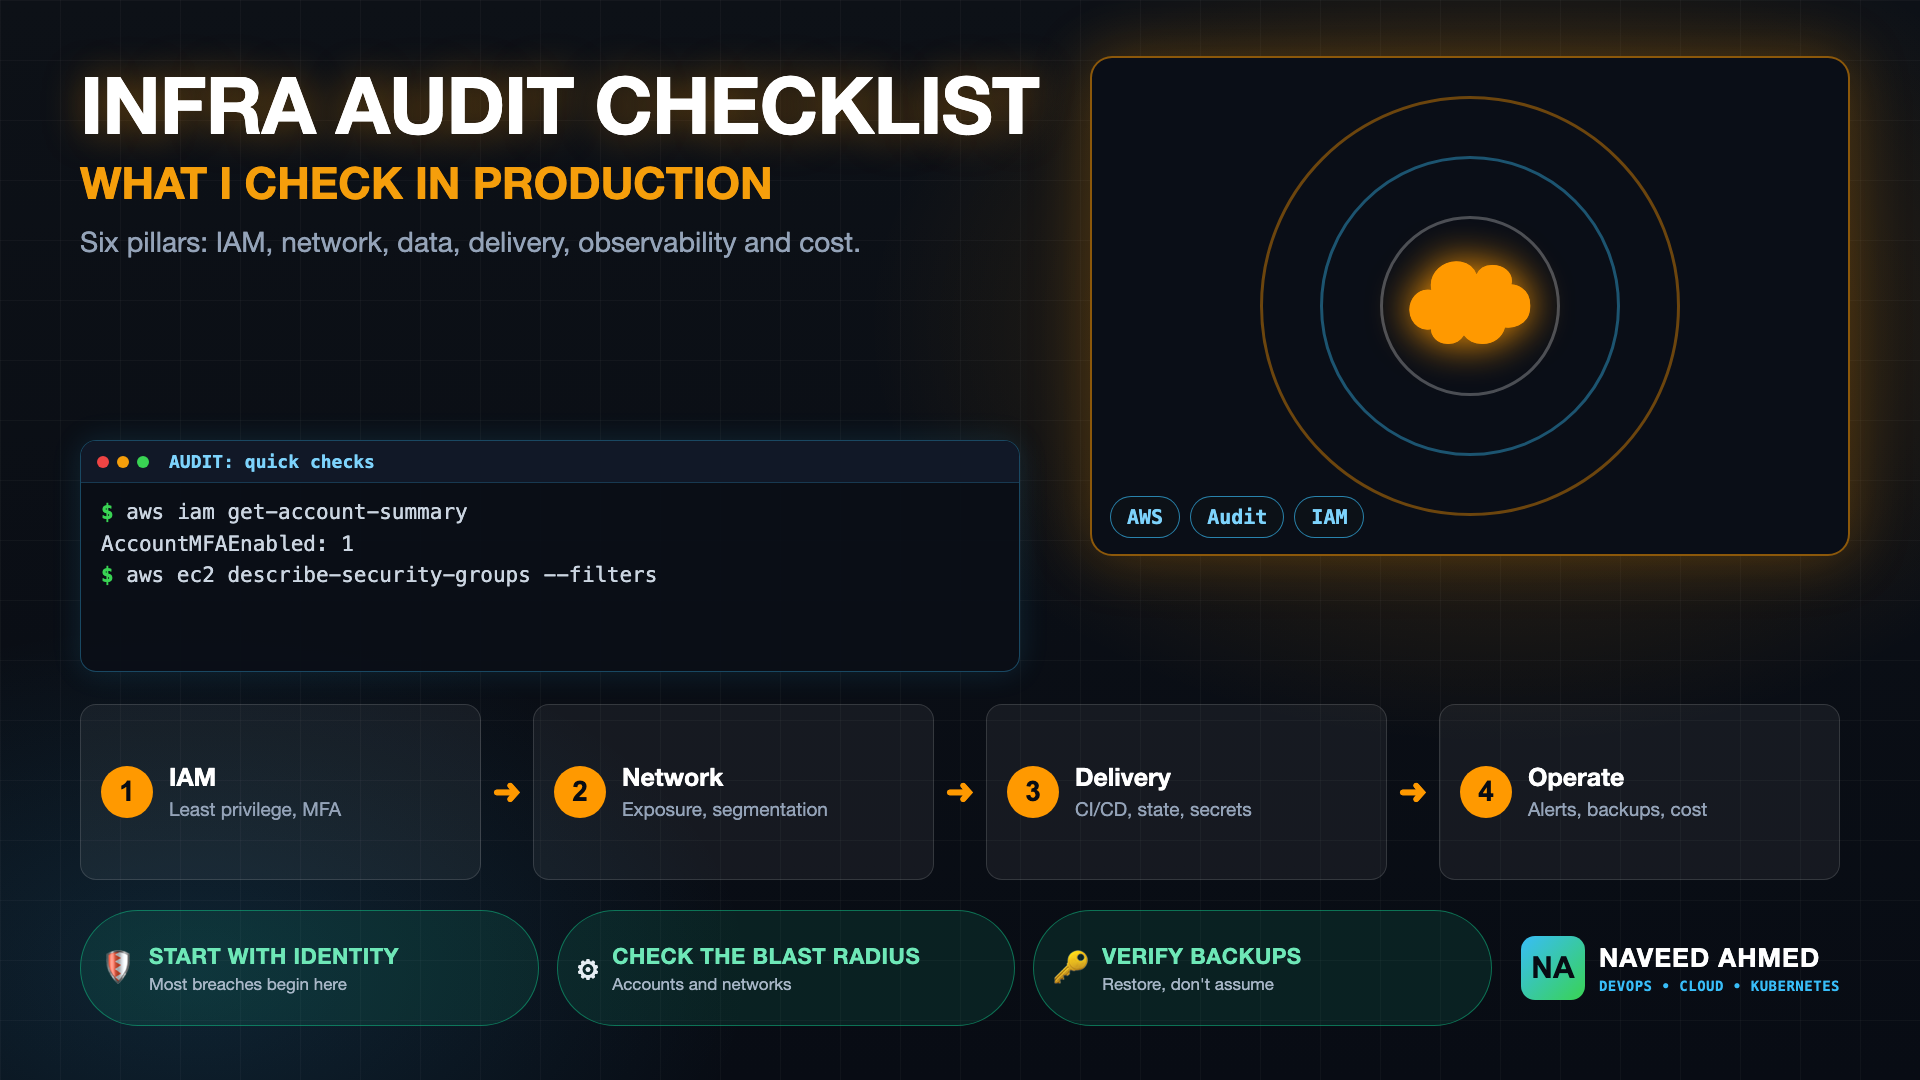
Infrastructure Audit Checklist: The 6 Pillars of Production Health
My audit framework is derived from over a decade of hands-on production engineering and aligns with the AWS Well-Architected Framework and CIS Benchmarks.
1. Identity, Access & Perimeter Defense
- Root Account Lockdown: Is root MFA hardware-backed (FIDO/YubiKey)? Are root API access keys completely deleted?
- IAM Least Privilege: Zero wildcard
"Action": "*"permissions. Are developer credentials routed through AWS IAM Identity Center (SSO) with temporary session credentials? - Access Key Hygiene: Automated alert for any IAM user access key older than 90 days.
- Network Isolation: Zero databases (RDS, Aurora, MongoDB) or caches (ElastiCache, Redis) residing in public subnets or accessible via public IP.
- Security Groups: Ensure no security groups have ingress
0.0.0.0/0on administrative ports (SSH 22, RDP 3389, Kube-apiserver 6443). - WAF & Shield: AWS WAF rules active against OWASP Top 10, rate limiting brute-force endpoints.
2. Cluster Architecture & Pod Security
- Pod Security Standards: Are namespaces enforcing
baselineorrestrictedstandards? Zero containers running as root (runAsNonRoot: true). - Resource Limits & Requests: Every single pod must define explicit
requestsandlimitsfor both CPU and memory to prevent noisy-neighbor starvation and node eviction. - Probe Configuration: Validation that liveness probes are shallow and readiness probes correctly detach traffic during startup.
- Control Plane Redundancy: Multi-AZ control plane and worker nodes distributed across at least 3 Availability Zones with topology spread constraints.
- Network Policies: Default-deny ingress/egress network policies preventing lateral movement between namespaces.
3. High Availability & Disaster Recovery
- RTO & RPO Benchmarks: Documented, tested Recovery Time Objective (RTO) and Recovery Point Objective (RPO).
- Automated Backup Drills: Are database snapshots regularly restored into isolated test environments to verify data integrity?
- Cross-Region Replication: Critical S3 buckets and database backups mirrored to an alternate AWS region with KMS cross-region keys.
- Circuit Breakers: Client timeouts, retries with exponential backoff, and jitter configured on all inter-service communications.
4. CI/CD, Observability & FinOps
- CI/CD Security: Keyless OIDC authentication for GitHub Actions, immutable container tags, automated container vulnerability scanning with Trivy.
- Observability (The 4 Golden Signals): Dashboards and PagerDuty alerts configured for Latency, Traffic, Errors, and Saturation across all user-facing services.
- FinOps & Rightsizing: Zero unattached EBS volumes, legacy gp2 migrated to gp3, VPC endpoints configured to eliminate NAT Gateway fees, and Karpenter Spot consolidation active.
Have questions about this architecture or scaling your infrastructure?
Whether you're planning a complex cloud migration, optimizing Kubernetes reliability, or designing autonomous AI workflows, I'm always open to discussing architecture and technical challenges with engineering teams.
Connect with Naveed on LinkedIn →How I Run the Audit: Scope, Evidence and Reporting
A checklist is only useful if the audit around it is disciplined. I start by agreeing the scope in writing: which accounts, clusters and environments are in, which are out, and what the business considers critical. Access is read-only. I ask for a role that can inspect configuration but cannot change it, which also makes the engagement easy for security teams to approve.
Evidence comes from three places. First, configuration exported straight from the platform, such as IAM policies, security group rules, cluster settings and backup schedules. Second, infrastructure-as-code repositories and pipeline definitions, to see how things are meant to be built. Third, short interviews with the people who run the system, because the gap between what is documented and what actually happens is often where the real risk lives.
Every finding is recorded with the evidence, the affected resources and a severity. I rate severity by combining likelihood and impact: a publicly reachable database with no authentication is critical, while an untagged resource is low. The audit never changes production. It produces a report that the owning teams can act on.
What the final report contains
The report has an executive summary in plain language, a risk register that lists every finding with its evidence, severity, owner and recommended fix, a prioritized roadmap that separates quick wins from structural work, and an appendix of raw evidence so every statement can be checked. I keep the jargon at the bottom and the decisions at the top, so leadership can decide and engineers can act from the same document.
Turning Audit Findings into a Remediation Plan
The report is not the deliverable; the improvement is. I group findings into quick wins that take hours, such as closing an open port or enabling MFA, and structural work that needs design, such as redesigning backups or splitting a shared account. Each item gets an owner and a target date, and the highest severity items go first regardless of effort.
After fixes land, verify them with the same evidence you used to find them, then schedule the next review. Infrastructure drifts, so an audit is most valuable as a recurring habit rather than a one-time event. If cost came up in the findings, the guide to reduce AWS costs shows how to cut spend without hurting reliability. If your infrastructure is defined in code, a clear Terraform AWS architecture makes many of these checks easier, and the AWS zero downtime migration playbook covers audits as part of a move to AWS.
Frequently Asked Questions
What is the primary deliverable of a DevOps infrastructure audit?
The primary deliverable is an executive and technical findings report detailing: 1) High-severity security vulnerabilities and immediate exposure risks, 2) Single Points of Failure (SPOFs) threatening SLA uptime, 3) Concrete FinOps cost-reduction opportunities with projected dollar savings, and 4) A prioritized 30/60/90-day remediation roadmap.
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
How long does a production DevOps infrastructure audit take?
A thorough audit of a cloud environment (AWS/GCP, Kubernetes, CI/CD, and Observability) typically takes 5 to 10 business days, consisting of read-only architecture inspection, automated configuration scans, and interviews with lead engineers and stakeholders.
Does performing an infrastructure audit require write access or cause downtime?
Never. A professional infrastructure audit is performed entirely via read-only IAM roles (e.g. AWS SecurityAudit and ViewOnlyAccess policies) and non-invasive inspection tools. It requires zero downtime and makes zero changes to live production systems.