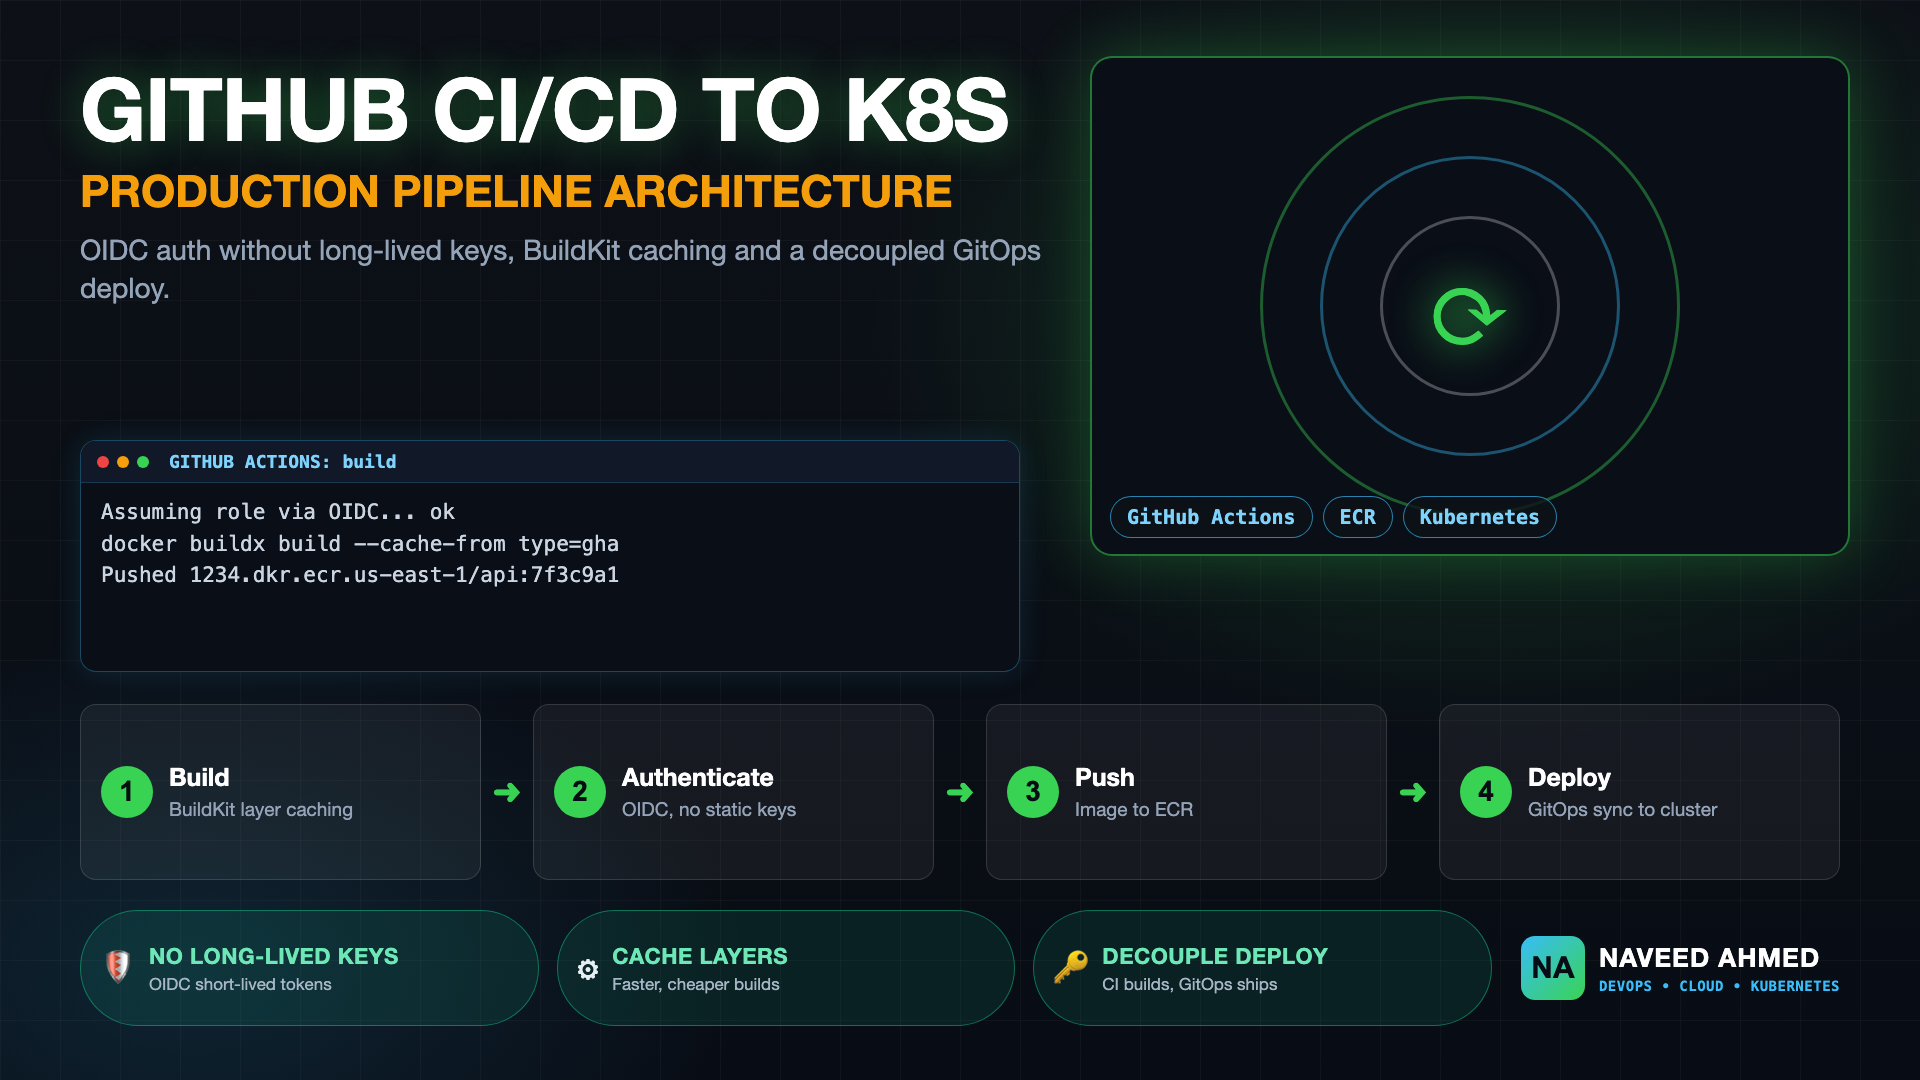
Terraform AWS Architecture for a Production SaaS: Modular, Multi-Region and Secure
Terraform AWS Architecture: The Enterprise Multi-Account IaC Blueprint
Before executing production plans, benchmark your review speed in our interactive arcade game: Terraform Plan or Destroy?. Also read our comprehensive PR review runbook: How to Review Terraform Plans Without Destroying Production.
An enterprise SaaS architecture cannot survive in a single AWS account. We decouple infrastructure using AWS Organizations into isolated accounts:
- Management / Root Account: Billing, Organization SCPs, AWS IAM Identity Center (SSO). Zero workloads.
- Security & Audit Account: Centralized CloudTrail, GuardDuty, AWS Config, and KMS root keys.
- Shared Services Account: CI/CD runners, container registry (ECR), DNS root zones, artifact repositories.
- Development / Staging / Production Accounts: Dedicated VPCs, isolated IAM roles, and completely independent Terraform remote state backends.
Zero-Blast-Radius S3 & DynamoDB Backend
Every environment and service layer maintains its own state file. Never share a single terraform.tfstate across environments.
# backend.tf - Secured with KMS, versioning, and DynamoDB state locking
terraform {
  backend "s3" {
    bucket         = "acme-corp-prod-tfstate-347166961665"
    key            = "compute/eks-cluster/terraform.tfstate"
    region         = "us-east-1"
    dynamodb_table = "acme-corp-prod-tflocks"
    encrypt        = true
    kms_key_id     = "arn:aws:kms:us-east-1:347166961665:key/tfstate-key"
  }
}
Mandatory S3 Bucket Policy: Deny all non-TLS traffic (aws:SecureTransport: false) and enforce server-side encryption with AWS KMS.
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
Directory Hierarchy: Decoupling Lifecycles
Infrastructure components have vastly different lifecycles. A VPC changes twice a year; an EKS nodegroup or Helm release changes daily. Grouping them together is dangerous.
environments/
├── live/
│   ├── prod/
│   │   ├── 00-bootstrap/         # IAM roles, KMS keys, baseline policies
│   │   ├── 10-network/           # VPC, Transit Gateway, NAT Gateways
│   │   ├── 20-database/          # Aurora PostgreSQL, ElastiCache Redis
│   │   ├── 30-compute/           # EKS cluster, Karpenter provisioners
│   │   └── 40-addons/            # ArgoCD, ExternalDNS, Cert-Manager
│   └── staging/
└── modules/
    ├── vpc/
    ├── aurora-postgresql/
└── eks-cluster/Automated Drift Detection & CI/CD Guardrails
Every pull request triggers an automated validation pipeline before any engineer can apply changes:
- Static Analysis & Security: Run
tflint,checkov, andtfsecto catch open security groups (0.0.0.0/0on port 22) and unencrypted EBS volumes before review. - Cost Estimation: Run
infracoston PRs to provide exact monthly dollar deltas for infrastructure additions. - Speculative Plan: Run
terraform planvia GitHub Actions with AWS OIDC, posting structured diff outputs directly into the GitHub pull request comment.
terraform plan -detailed-exitcode -no-color || exit_code=$?
if [ $exit_code -eq 2 ]; then
  echo "CRITICAL: Infrastructure drift detected in production!"
  # Dispatch alert to SRE webhook
fi
Have questions about this architecture or scaling your infrastructure?
Whether you're planning a complex cloud migration, optimizing Kubernetes reliability, or designing autonomous AI workflows, I'm always open to discussing architecture and technical challenges with engineering teams.
Connect with Naveed on LinkedIn →Module Versioning and Promotion Across Environments
A good Terraform AWS architecture separates what changes often from what must stay stable. Reusable modules should be versioned, and each environment should pin the version it uses. That lets you test a module change in development, promote it through staging and reach production only after it has proven itself, instead of changing every environment at once.
module "network" {
  source  = "git::https://example.com/infra-modules.git//network?ref=v1.4.2"
  # Pin an immutable tag. Never reference a moving branch such as ?ref=main.
  cidr_block = var.vpc_cidr
}
Treat a module release like any other software release: write a short changelog, bump the version, and open a pull request in each environment's repository to adopt it. If a release goes wrong, rolling back is a one-line change to the previous tag.
Recovering From Terraform State Problems
State is the one file you cannot afford to lose, so plan for the bad day. Enable versioning on the S3 state bucket so every previous state file can be restored, and restrict who can delete or overwrite it. If a pipeline dies mid-apply and leaves a lock behind, confirm that no apply is still running before using terraform force-unlock, because forcing a lock while another run is active can corrupt state.
When a resource exists in AWS but not in state, use terraform import instead of recreating it. When a resource was removed from code on purpose, use terraform state rm deliberately and record why. Keep a break-glass role, audited and rarely used, for the day the normal pipeline cannot run.
Testing and Policy Checks in CI for Terraform on AWS
Automation should catch mistakes before a human has to. On every pull request, run terraform fmt -check, terraform validate and a linter such as TFLint, then produce a plan and attach it for review. Run policy-as-code checks against the plan, for example with OPA and Conftest, to block changes such as public S3 buckets, unencrypted volumes or overly broad IAM policies.
Apply only from the main branch, after approval, using short-lived credentials. Give each AWS account its own least-privilege role assumed through OIDC, so a pipeline for one environment cannot touch another. Combine this with scheduled plans that report drift, and use an infrastructure audit checklist to review the result from the outside. For the cost side of the same estate, see how to reduce AWS costs, and for moving workloads into a new account structure read the AWS zero downtime migration playbook.
Frequently Asked Questions
Why should Terraform state be split across multiple accounts and directories?
Splitting Terraform state across multiple AWS accounts and directory layers minimizes the blast radius of any individual apply operation. Monolithic state files result in slow plan times (15+ minutes), dangerous concurrency locks, and catastrophic failure modes where an error in a shared resource damages unrelated production systems.
What is the best way to handle secrets in Terraform without storing them in plaintext state?
Never pass secrets directly through Terraform variables or resources if avoidable, because Terraform state files store sensitive values in unencrypted JSON. Instead, manage secrets via AWS Secrets Manager or HashiCorp Vault, inject secret ARNs into application manifests, and use tools like External Secrets Operator (ESO) inside Kubernetes to retrieve secrets at runtime.
How do you detect and prevent Terraform infrastructure drift in production?
Drift is detected by running automated scheduled CI/CD jobs (e.g. via GitHub Actions or Spacelift) executing terraform plan -detailed-exitcode daily. If exit code 2 is returned (indicating drift), an alert is dispatched to Slack/PagerDuty. Prevention is achieved by strictly revoking AWS console write access in production accounts.