The Complete Kubernetes Runbook: 12 Production Failures, Root Cause and Fix
Kubernetes Runbook Navigation: 12 Production Failure Scenarios
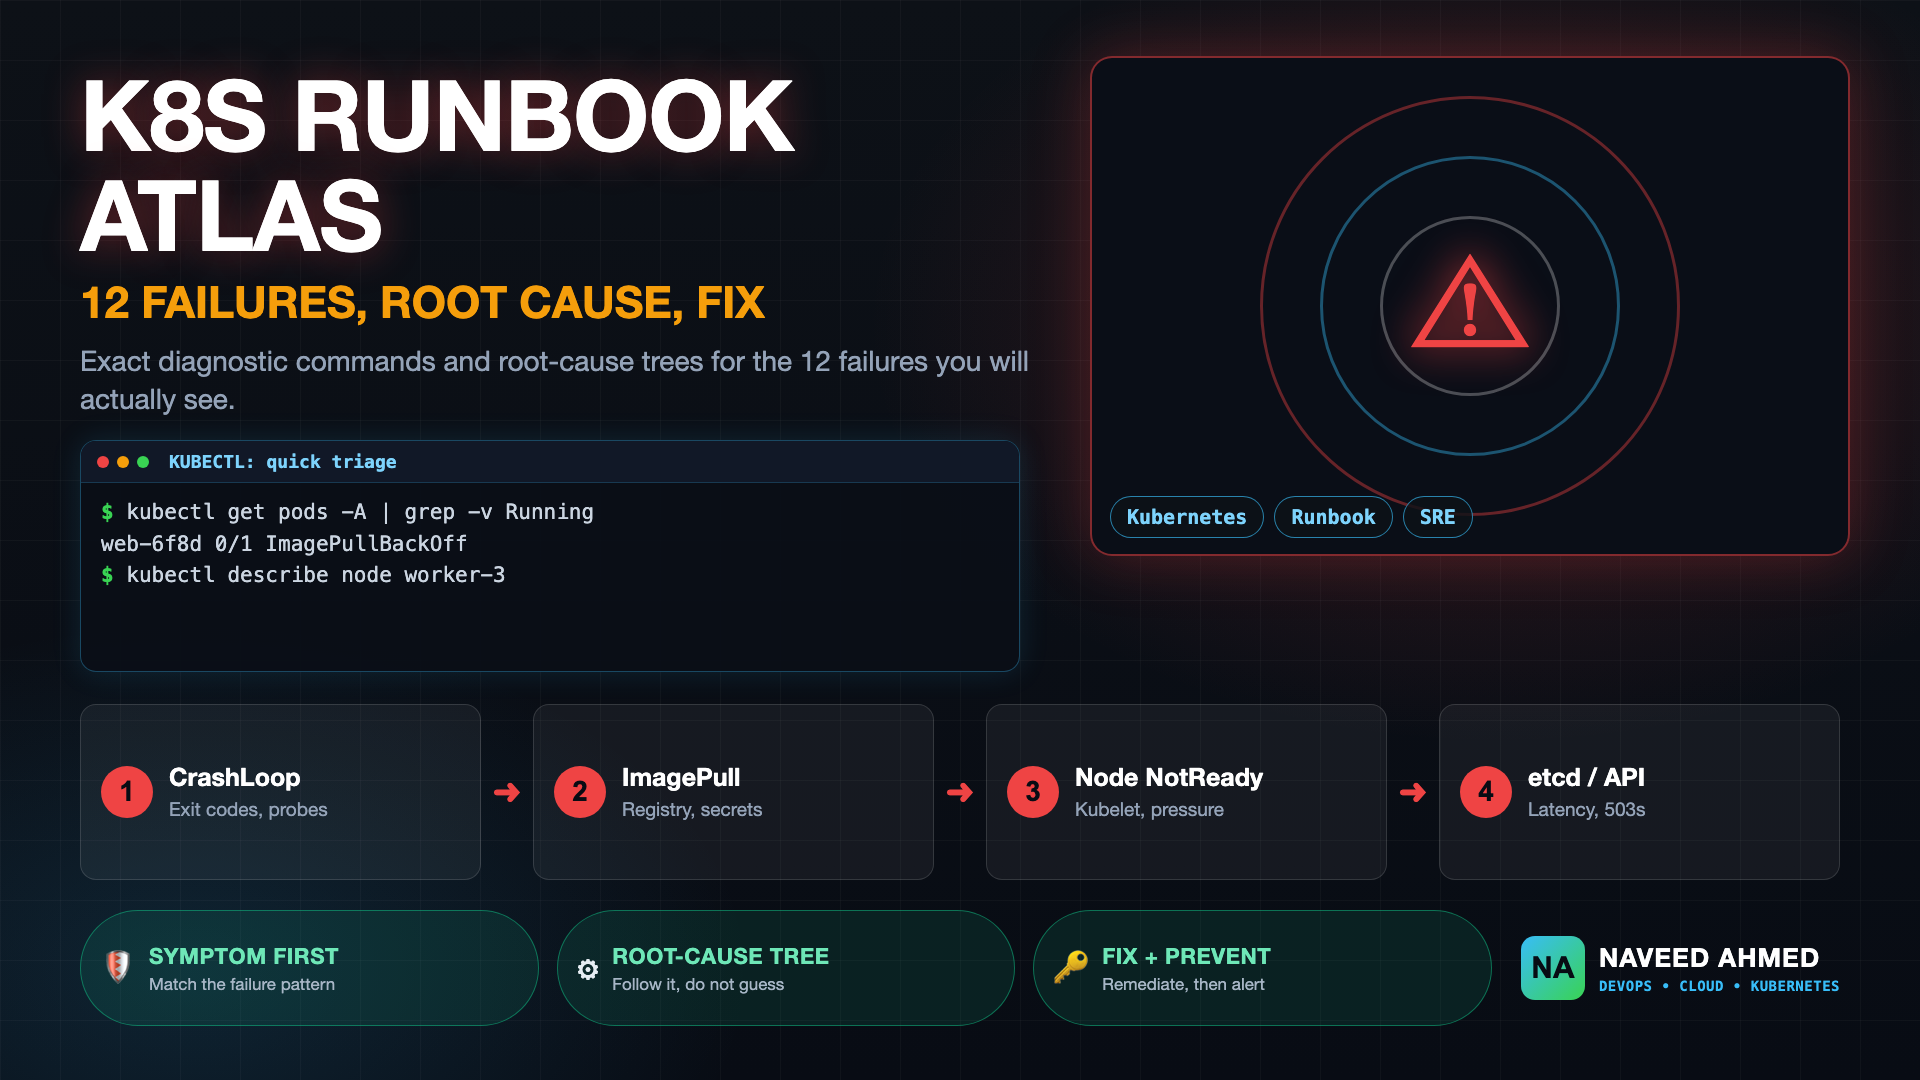
Click any failure pattern below to jump directly to its diagnostic runbook and remediation commands:
| Failure Pattern | Severity | Common Root Cause |
|---|---|---|
| 1. CrashLoopBackOff & Container Termination | P1 / Critical | OOMKilled (exit code 137), failed liveness probe, missing ConfigMap |
| 2. ImagePullBackOff & ErrImagePull | P2 / High | Registry rate limits, missing imagePullSecrets, image tag typo |
| 3. Node NotReady & Kubelet Heartbeat Failures | P1 / Critical | Containerd hang, disk/inode pressure, kernel OOM deadlock |
| 4. etcd Performance Degradation & Latency Spikes | P1 / Critical | Disk fsync latency >10ms, leader election timeouts, DB fragmentation |
| 5. Kube-Apiserver Unreachable / 503 Errors | P1 / Critical | Mutating webhook deadlocks, etcd saturation, API priority queue exhaustion |
| 6. PVC / StorageClass Stuck in Pending | P2 / High | Multi-AZ EBS volume mismatch, missing CSI node driver, VolumeAttachment lock |
| 7. Karpenter / Autoscaler Node Provisioning Failures | P2 / High | Insufficient cloud instance capacity (ICE), IAM instance profile mismatch |
| 8. ArgoCD Out-of-Sync & Infinite Sync Loops | P3 / Medium | Mutating admission webhook modifying fields, CRD schema drift |
| 9. Network Policy Lockouts & CoreDNS Timeouts | P1 / Critical | Default-deny ingress/egress policy locking out kube-dns UDP port 53 |
| 10. ResourceQuota Exceeded & Scheduling Deadlocks | P2 / High | Namespace CPU/Memory requests sum exceeded, pods without limits rejected |
| 11. HPA Not Scaling & Metrics Server Failures | P2 / High | Missing metrics-server, container missing resources.requests.cpu |
| 12. Control Plane TLS Certificate Expiration | P1 / Critical | 1-year kubeadm root/peer certificates expired, kubelet client cert rejected |
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
CrashLoopBackOff & Container Termination State
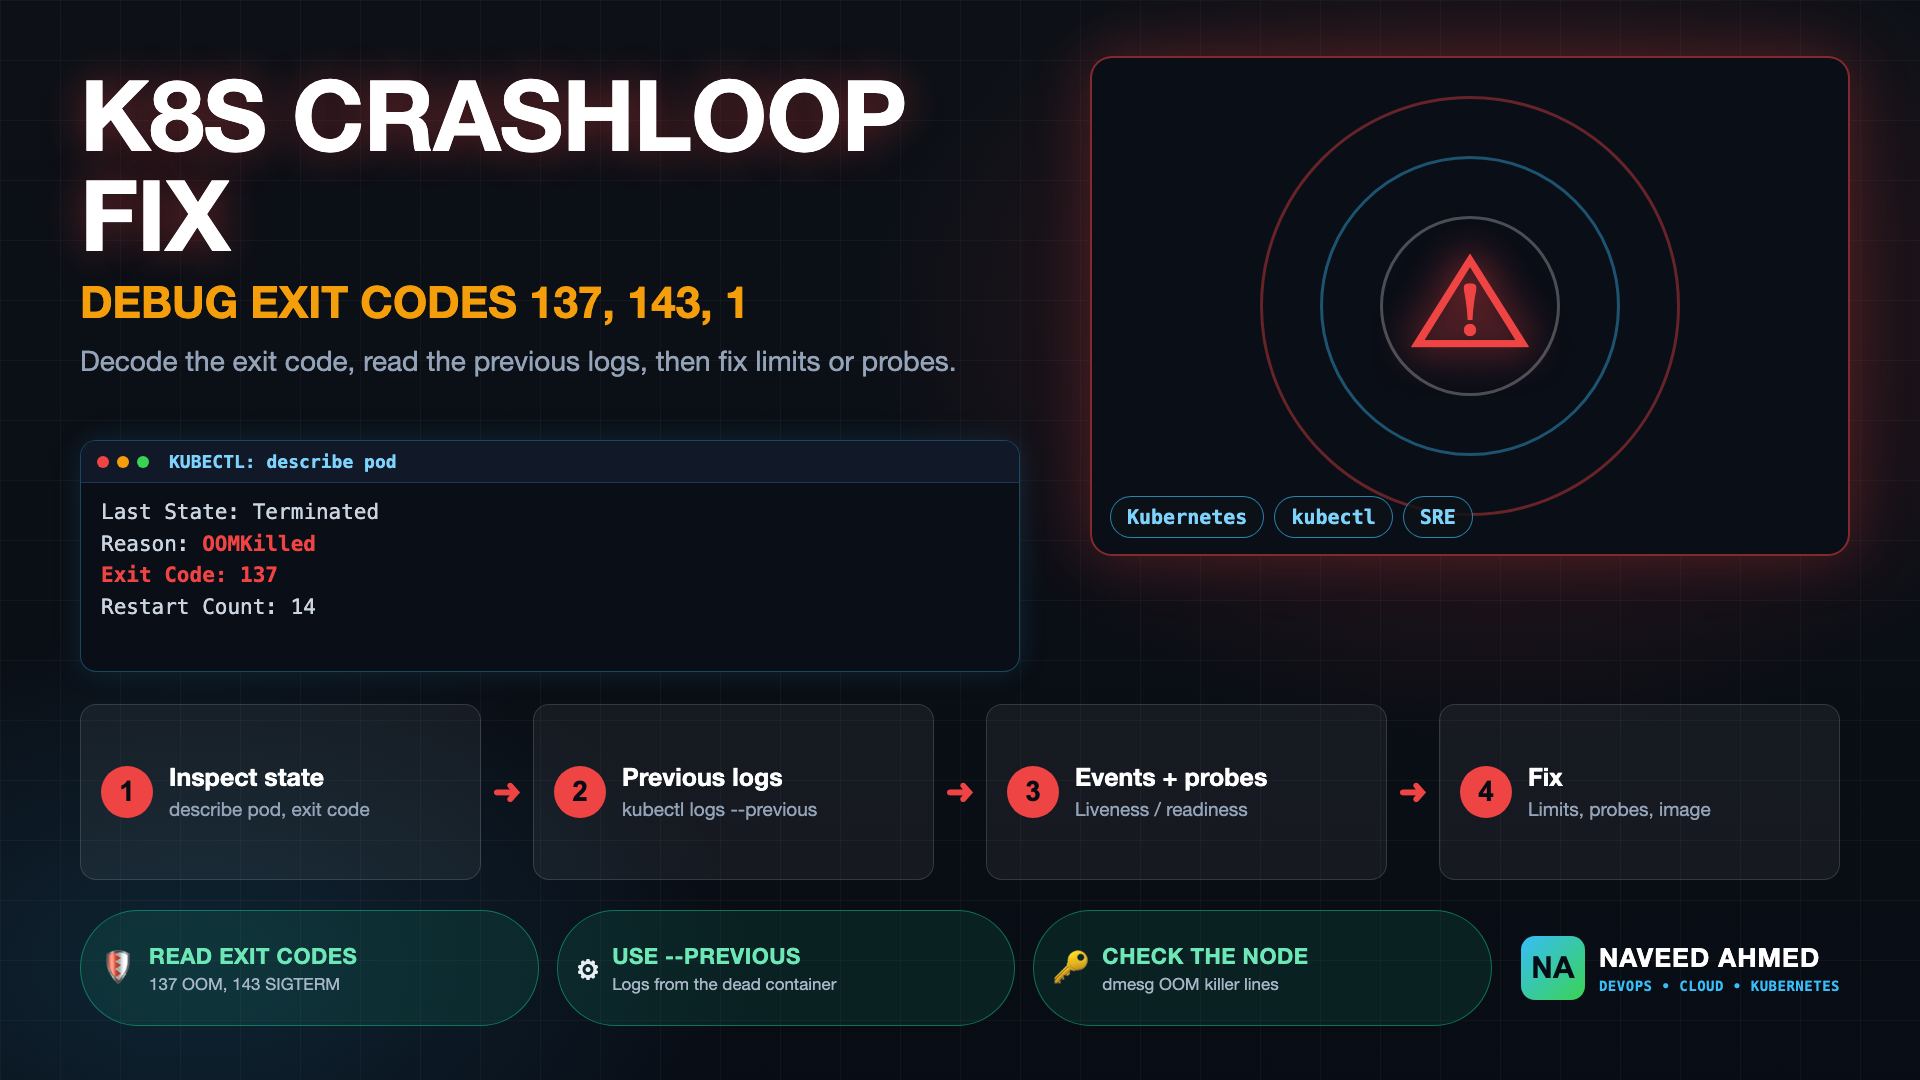
CrashLoopBackOff indicates that a pod's container successfully passes scheduling and image pulling but terminates repeatedly upon process execution. Kubernetes enforces exponential backoff delays (10s, 20s, 40s up to 300s) between restart attempts.
1. Diagnostic CLI Commands
kubectl get pod <pod-name> -n <namespace> -o jsonpath='{range .status.containerStatuses[*]}{.name}{"\tExitCode:"}{.state.waiting.message}{.lastState.terminated.exitCode}{"\tReason:"}{.lastState.terminated.reason}{"\n"}{end}'kubectl logs <pod-name> -n <namespace> --previous --tail=100# Run on the host node or via ephemeral debug container:
dmesg -T | grep -E -i "oom_reaper|killed process|out of memory"2. Exit Code Decoder
- Exit Code 137: Container was terminated by
SIGKILL(128 + 9). In many cases, this is anOOMKilledtrigger from the Linux kernel cgroup controller when memory limits are exceeded. - Exit Code 143: Container received
SIGTERM(128 + 15). Kubelet gracefully terminated the pod, often due to a failed liveness probe or preemption. - Exit Code 1 / 2: Application-level runtime exception (missing configuration file, unhandled Promise rejection, database connection failure).
3. Permanent Remediation
If exit code is 137, increase memory limits in the deployment manifest or profile application heap allocation. If exit code is 143 due to probe failure, adjust initialDelaySeconds and failureThreshold to allow slow application bootstrap:
livenessProbe:
  httpGet:
    path: /healthz
    port: 8080
  initialDelaySeconds: 45   # Increase from default 0-10s
  periodSeconds: 10
failureThreshold: 5 # Allow up to 5 consecutive failures before killingImagePullBackOff & ErrImagePull
ImagePullBackOff occurs when kubelet cannot pull the specified container image from the container registry (Docker Hub, AWS ECR, GitHub Packages) onto the target worker node.
1. Diagnostic CLI Commands
kubectl describe pod <pod-name> -n <namespace> | grep -A 10 "Events:"2. Root Cause Decision Tree
- 401 / 403 Forbidden: Missing or expired
imagePullSecrets. For AWS ECR, the IAM node role lacksecr:GetAuthorizationTokenandecr:BatchGetImage. - 429 Too Many Requests: Docker Hub anonymous rate limiting (100 pulls per 6 hours per IP). Remediate by authenticating or proxying through an internal harbor/ECR pull-through cache.
- 404 Not Found: Image tag typo or multi-architecture mismatch (e.g. attempting to run an
arm64image on anamd64node).
3. Permanent Remediation
# Create registry secret and patch default service account:
kubectl create secret docker-registry regcred \
  --docker-server=<your-registry-server> \
  --docker-username=<your-user> \
  --docker-password=<your-token> \
  -n <namespace>

# Add to pod deployment:
spec:
  imagePullSecrets:
- name: regcredNode NotReady & Kubelet Heartbeat Failures
NotReady when the master control plane has not received a node lease update from the kubelet service within the node-monitor-grace-period (default 40s).
1. Diagnostic CLI Commands
# Check node condition reasons:
kubectl describe node <node-name> | grep -A 8 "Conditions:"

# SSH into the node and inspect kubelet logs:
journalctl -u kubelet -n 150 --no-pager

# Check containerd / runtime daemon status:
systemctl status containerd
2. Remediation
If containerd has hung on zombie shim processes:
sudo systemctl restart containerd
sudo systemctl restart kubelet
If the node is under DiskPressure (filesystem >85% capacity):
# Clean dangling images and stopped containers:
crictl rmi --prune
df -h /var/lib/containerd /var/lib/kubeletetcd Performance Degradation & Latency Spikes
1. Diagnostic CLI Commands
# Check etcd member health and cluster alarms:
etcdctl endpoint health --write-out=table
etcdctl alarm list

# Check disk fsync latency warnings in logs:
journalctl -u etcd | grep -E "took too long|lost leader|server is likely overloaded"
2. Remediation
Defragment the etcd database and disarm storage quota alarms:
# Defragment all endpoints:
etcdctl defrag --cluster

# Disarm alarms once defragmentation frees space:
etcdctl alarm disarmKube-Apiserver Unreachable / 503 Errors
1. Diagnostic CLI Commands
# Identify misconfigured validating or mutating webhooks:
kubectl get validatingwebhookconfigurations,mutatingwebhookconfigurations

# Check apiserver container logs:
kubectl logs -n kube-system -l component=kube-apiserver --tail=100 | grep -E "webhook|timeout|503"
2. Emergency Remediation
If a third-party webhook (e.g., Istio, Cert-Manager, or policy agent) is unreachable and configured with failurePolicy: Fail, it blocks all cluster admissions. Change policy to Ignore in an emergency:
kubectl patch validatingwebhookconfiguration <webhook-name> \
--type='json' -p='[{"op": "replace", "path": "/webhooks/0/failurePolicy", "value": "Ignore"}]'PVC & StorageClass Stuck in Pending
Pending when the CSI provisioner cannot create an underlying block device or when volume topology constraints (e.g. AWS Availability Zone mismatch) prevent pod scheduling.
1. Diagnostic CLI Commands
kubectl describe pvc <pvc-name> -n <namespace>
kubectl get events -n <namespace> --field-selector reason=FailedBinding
2. Remediation
Ensure your StorageClass uses volumeBindingMode: WaitForFirstConsumer. This prevents the cloud provider from creating an EBS/Azure disk in us-east-1a when the pod is scheduled on a worker node in us-east-1b:
apiVersion: storage.k8s.io/v1
kind: StorageClass
metadata:
  name: ebs-sc
provisioner: ebs.csi.aws.com
volumeBindingMode: WaitForFirstConsumer # Critical for multi-AZ clustersKarpenter / Autoscaler Node Provisioning Failures
1. Diagnostic CLI Commands
# Check Karpenter controller logs:
kubectl logs -n karpenter -l app.kubernetes.io/name=karpenter --tail=100 | grep -E "ERROR|failed|capacity"

# Inspect unschedulable pod requirements:
kubectl get pods -A --field-selector status.phase=Pending
2. Remediation
Broaden your EC2NodeClass / NodePool instance types. Avoid pinning to a single instance family (e.g. m5.large). Allow Karpenter to select across multiple generation families and availability zones:
requirements:
  - key: "karpenter.k8s.aws/instance-category"
    operator: In
    values: ["c", "m", "r"]
  - key: "karpenter.k8s.aws/instance-generation"
    operator: Gt
    values: ["4"]
  - key: "karpenter.sh/capacity-type"
    operator: In
values: ["spot", "on-demand"]ArgoCD Out-of-Sync & Infinite Sync Loops
1. Diagnostic CLI Commands
argocd app diff <app-name> --hard-refresh
argocd app get <app-name> --show-operation-details
2. Remediation
Add an ignoreDifferences block in your ArgoCD Application manifest to ignore dynamic fields populated by cloud controllers:
spec:
  ignoreDifferences:
    - group: apps
      kind: Deployment
      jsonPointers:
- /spec/template/spec/containers/0/imagePullPolicyNetwork Policy Lockouts & CoreDNS Resolution Failures
1. Diagnostic CLI Commands
# Test DNS resolution from inside a debug pod:
kubectl run dns-test --rm -it --image=busybox:1.28 -- nslookup kubernetes.default

# Check CoreDNS pod status and logs:
kubectl get pods -n kube-system -l k8s-app=kube-dns
kubectl logs -n kube-system -l k8s-app=kube-dns --tail=50
2. Remediation
Ensure any default-deny egress NetworkPolicy includes an explicit rule permitting traffic to CoreDNS in the kube-system namespace:
egress:
  - to:
      - namespaceSelector:
          matchLabels:
            kubernetes.io/metadata.name: kube-system
        podSelector:
          matchLabels:
            k8s-app: kube-dns
    ports:
      - protocol: UDP
        port: 53
      - protocol: TCP
port: 53ResourceQuota Exceeded & Scheduling Deadlocks
ResourceQuota rejection occurs when an attempted deployment requests more aggregate CPU, memory, or object counts than permitted by the namespace quota.
1. Diagnostic CLI Commands
kubectl get resourcequota -n <namespace>
kubectl describe resourcequota -n <namespace>
2. Remediation
Identify pods consuming quota without active workloads, right-size requests, or increase the namespace quota specification via Infrastructure as Code.
HPA Not Scaling & Metrics Server Failures
<unknown>/50% target utilization when metrics-server is not installed or when target containers do not declare resources.requests.cpu.
1. Diagnostic CLI Commands
kubectl describe hpa <hpa-name> -n <namespace>
kubectl top pods -n <namespace>
2. Remediation
HPA cannot calculate percentage utilization without a baseline request. Always declare container CPU requests:
resources:
  requests:
    cpu: 250m
memory: 256MiControl Plane TLS Certificate Expiration
1. Diagnostic CLI Commands
kubeadm certs check-expiration2. Remediation
Renew all control plane certificates with zero downtime:
kubeadm certs renew all
# Restart static control plane pods:
sudo kill -s SIGHUP $(pidof kube-apiserver kube-controller-manager kube-scheduler)
Master Production Kubernetes Architecture
Level up your cluster operations with hands-on labs, architectural deep dives, and production incident triage drills on the Kubernetes Mastery Path.
Explore Kubernetes Mastery Path →How to Keep This Kubernetes Runbook Useful
A runbook that nobody maintains becomes a source of wrong answers. Store your copy in version control next to the manifests it describes, and review it after every incident: if responders deviated from the page, the page is wrong or incomplete. Link each alert to the matching section, so the first thing a responder sees is the right command, not a search box.
Rehearsal matters as much as documentation. Run game days where a teammate breaks something in a non-production cluster and the on-call engineer works from this Kubernetes runbook alone. Short timed drills in the kubectl practice game build the reflexes, the Kubernetes production issues checklist gives you a compact triage sequence for the first five minutes, and the Kubernetes learning path covers the fundamentals behind each failure.
Frequently Asked Questions
How should on-call teams prioritize between pod and node failures?
Always triage at the node layer first. A single Node NotReady or disk pressure event can cause dozens of cascading pod CrashLoopBackOff and probe failures. Restoring node stability typically self-heals healthy workload replicas.
What is the difference between liveness and readiness probes?
A liveness probe determines if the container process must be restarted by kubelet. A readiness probe determines if the pod should receive network traffic from the Service endpoint. Never use a liveness probe to check external database dependencies—use readiness probes to avoid death-spiral cascade restarts.