Every Kubernetes engineer has stared at it during a 2:00 AM incident: a pod status transitioning from Running to Error, and finally settling into the dreaded CrashLoopBackOff state.
CrashLoopBackOff is not an error code itself. It is a state condition indicating that Kubernetes attempted to launch your container, the process terminated, and the kubelet is backing off restarts with an exponential delay (10s, 20s, 40s, up to 5 minutes) to avoid overloading the node.
Kubernetes CrashLoopBackOff is not an error in itself. It is the status Kubernetes reports when a container keeps crashing and the kubelet is waiting longer between restart attempts, so the real question is always why the container exits. This runbook follows the order that finds the cause fastest.
Kubernetes CrashLoopBackOff Root Causes: Decoding Exit Codes
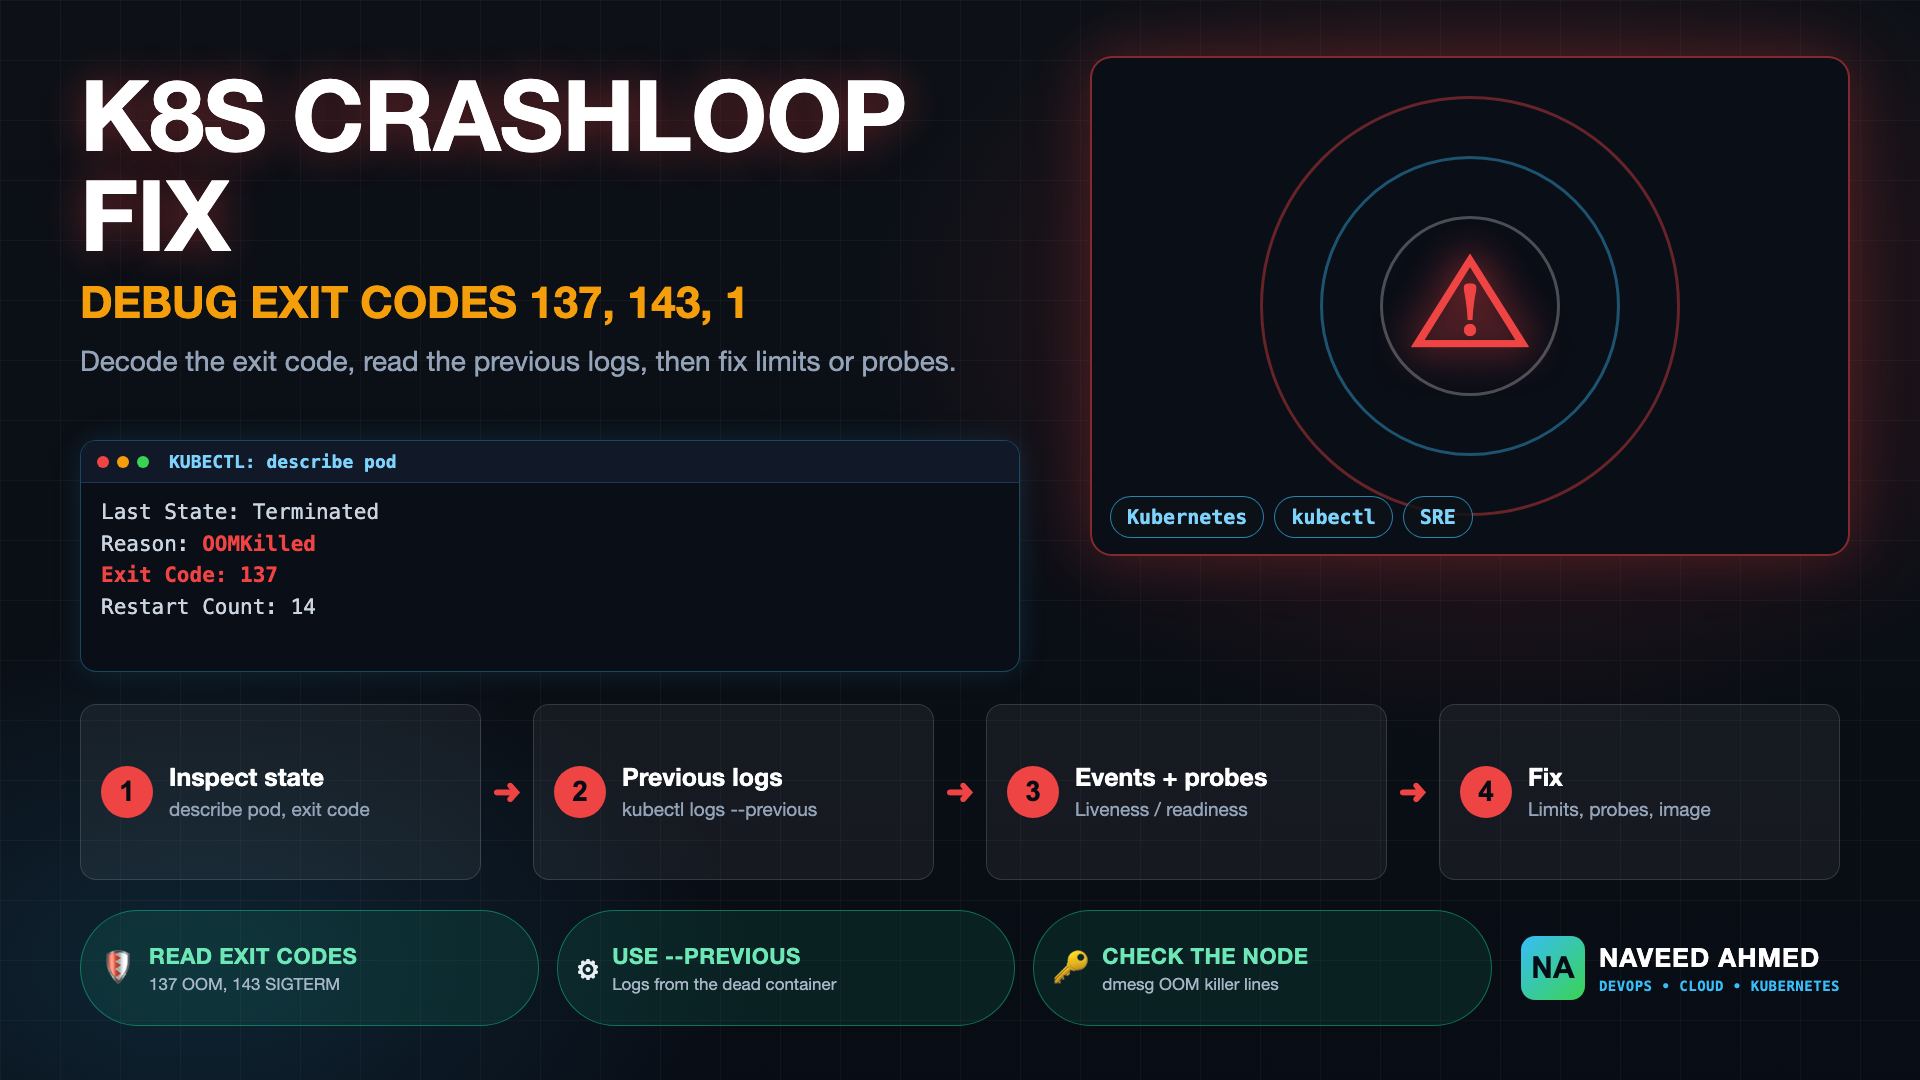
Before blindly restarting deployments or changing image tags, check the container exit code. The exit code reveals the exact mechanism of death:
| Exit Code | Name / Signal | Primary Root Cause |
|---|---|---|
| 137 | SIGKILL (128 + 9) |
OOMKilled — Linux kernel killed the container for exceeding limits.memory, or host memory pressure. |
| 143 | SIGTERM (128 + 15) |
Kubelet initiated termination due to failed liveness probe, preStop hook timeout, or rolling node draining. |
| 1 | Application Error | Uncaught exception, missing environment variable, syntax error, or unhandled database connection rejection. |
| 127 | Command Not Found | Entrypoint binary or startup command path is missing in the container image filesystem. |
| 139 | Segmentation Fault | C/Go binary memory corruption or incompatible native library dependencies (e.g. musl vs glibc on Alpine). |
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
Step 1: Inspect Container Termination State & Exit Code
Standard kubectl get pods only shows that restarts are incrementing. Query the container status subresource directly to extract the exact termination details:
# Extract termination reason and exit code from the last crashed instance
kubectl get pod <pod-name> -n <namespace> \
  -o jsonpath='{.status.containerStatuses[0].lastState.terminated}'
If you see the following JSON structure, you are facing an Out-Of-Memory termination:
{"exitCode": 137, "reason": "OOMKilled", "startedAt": "...", "finishedAt": "..."}Step 2: Capture Logs From the Previous Crashed Instance
When a pod restarts, running kubectl logs <pod-name> only streams logs from the newly spawned instance, which may look healthy before it dies. To see why the previous container crashed, use the --previous (or -p) flag:
# Stream stdout/stderr from the container that just died
kubectl logs <pod-name> -n <namespace> --previous --tail=100kubectl logs <pod-name> -c app-container --previous.
Step 3: Check Pod Events & Liveness Probe Failures
A frequent cause of Exit Code 143 is an overly aggressive Liveness Probe. If your application takes 45 seconds to establish its database connection pool during startup, but your probe has initialDelaySeconds: 15, the kubelet will declare the container dead and issue a SIGTERM while the app is still initializing.
# Inspect the latest 20 events recorded for the pod
kubectl describe pod <pod-name> -n <namespace> | grep -A 10 Events:
Watch out for warnings like:
Warning  Unhealthy  kubelet  Liveness probe failed: HTTP probe failed with statuscode: 500
Killing container with id containerd://app: Container failed liveness probe, will be restarted
The Solution: Decouple startup from ongoing health by implementing a startupProbe:
startupProbe:
  httpGet:
    path: /healthz
    port: 8080
  failureThreshold: 30
  periodSeconds: 2
# Liveness probe only activates AFTER startupProbe succeeds:
livenessProbe:
  httpGet:
    path: /healthz
    port: 8080
  initialDelaySeconds: 5
  periodSeconds: 10
Step 4: Investigate Node Kernel OOM Killer Events
When dealing with Exit Code 137, determine whether the container exceeded its own cgroup memory limit, or whether the entire worker node ran out of memory:
# 1. Identify which node is hosting the pod
NODE_NAME=$(kubectl get pod <pod-name> -n <namespace> -o jsonpath='{.spec.nodeName}')

# 2. Inspect node dmesg logs for kernel OOM invocations
kubectl get --raw "/api/v1/nodes/${NODE_NAME}/proxy/logs/dmesg" | grep -i -E "oom_killer|killed process"--max-old-space-size=768 or -XX:MaxRAMPercentage=75.
Step 5: Apply Runtime Memory & Probe Remediation
To permanently prevent CrashLoopBackOff:
- Set memory requests equal to limits for latency-sensitive microservices to achieve a Guaranteed Quality of Service (QoS) tier.
- Tune probe thresholds using
startupProbefor slow boot routines. - Establish Prometheus alerts on container memory approaching limits:
container_memory_working_set_bytes / kube_pod_container_resource_limits{resource="memory"} > 0.85
👉 Practice Scenario: Silent OOMKilled & CrashLoopBackOff on Interview Hub →
Preventing Kubernetes CrashLoopBackOff Before It Pages You
Fixing a crash loop at 3 AM is expensive, and most of them are preventable in the pod spec and the release process.
Right-size requests and limits
Set memory limits from observed usage, not guesses. Look at peak working-set memory over a representative period, add headroom, and revisit after significant releases. A limit that is too tight is the most common reason a healthy application is OOMKilled under load.
Design probes that do not kill healthy pods
Use a startup probe for slow-starting applications so the liveness probe does not restart a container that is still booting. Keep liveness checks cheap and local. If a liveness probe depends on a database or another service, one outage can restart every replica at once.
Shut down gracefully
Handle SIGTERM, finish in-flight requests and set terminationGracePeriodSeconds to match how long the application really needs. A container that ignores SIGTERM is eventually killed with SIGKILL, which appears as exit code 137 even when memory is fine.
Roll out changes safely
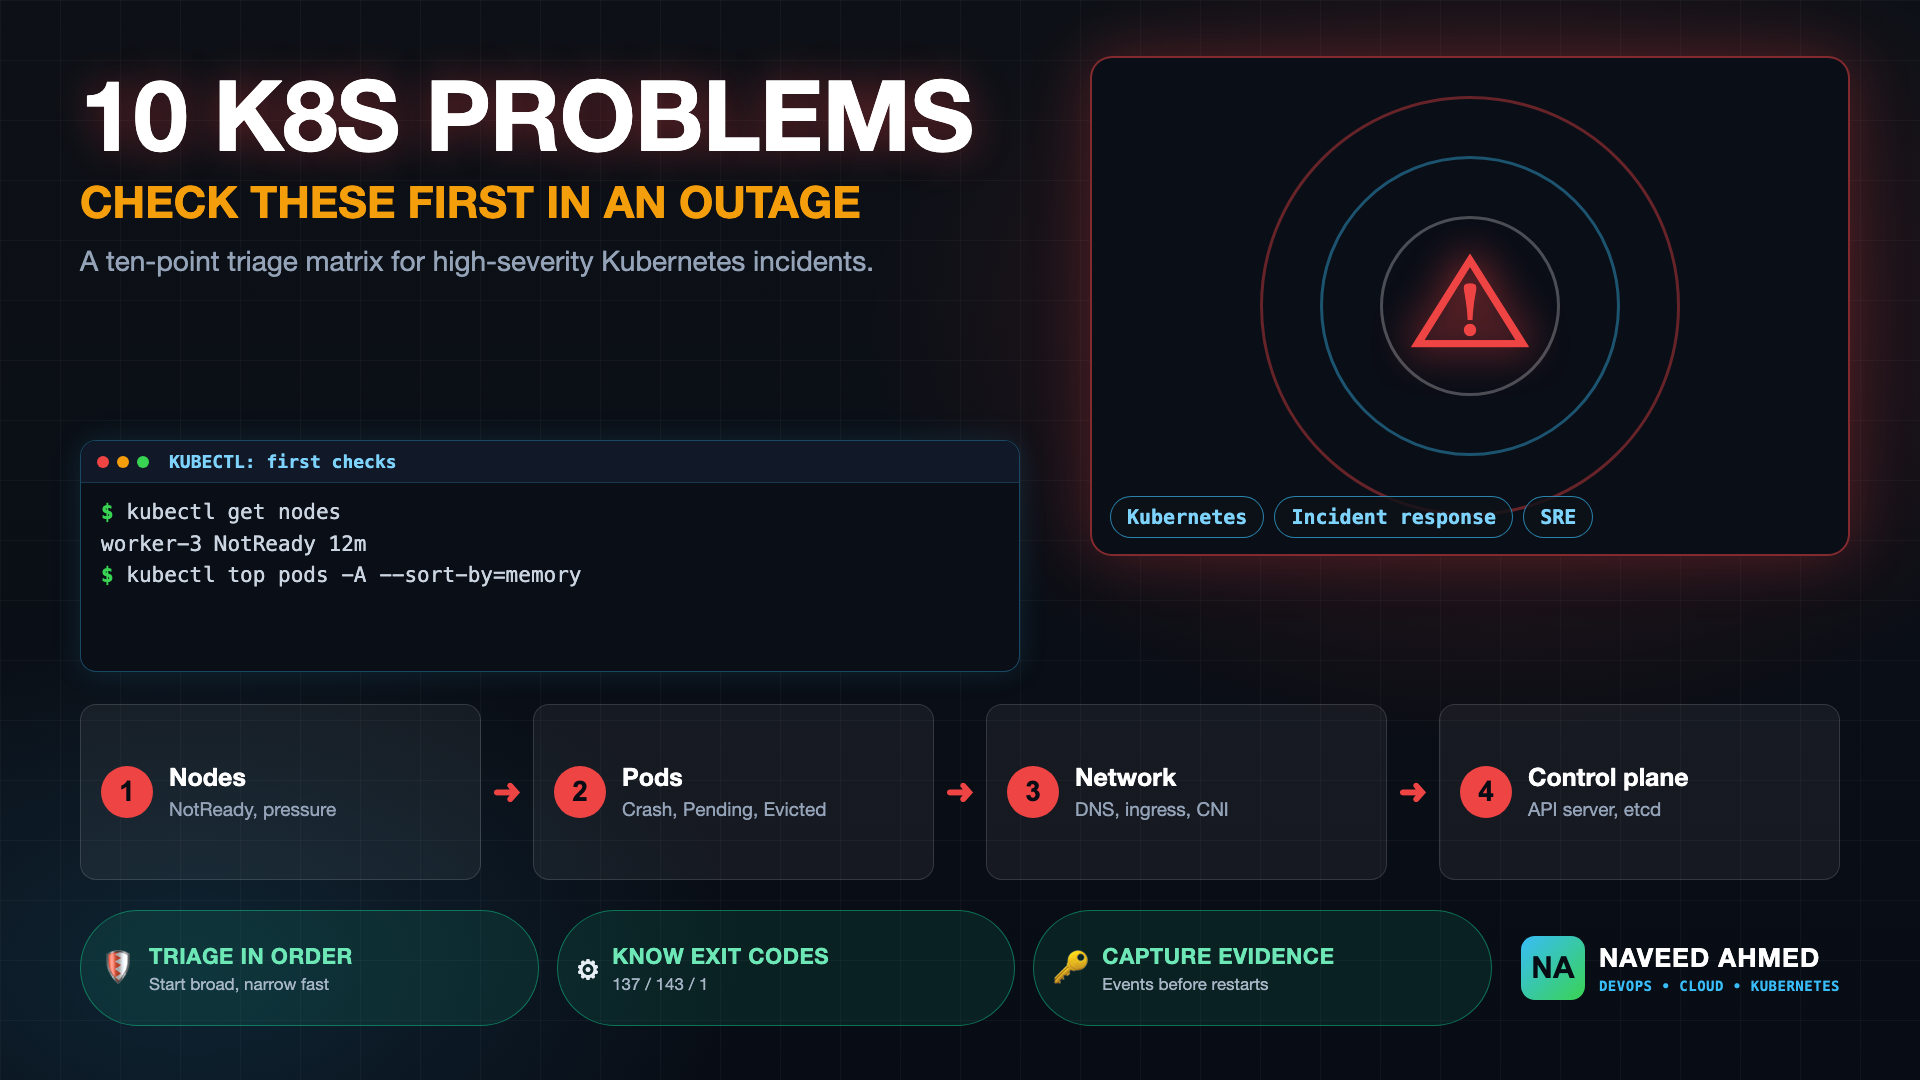
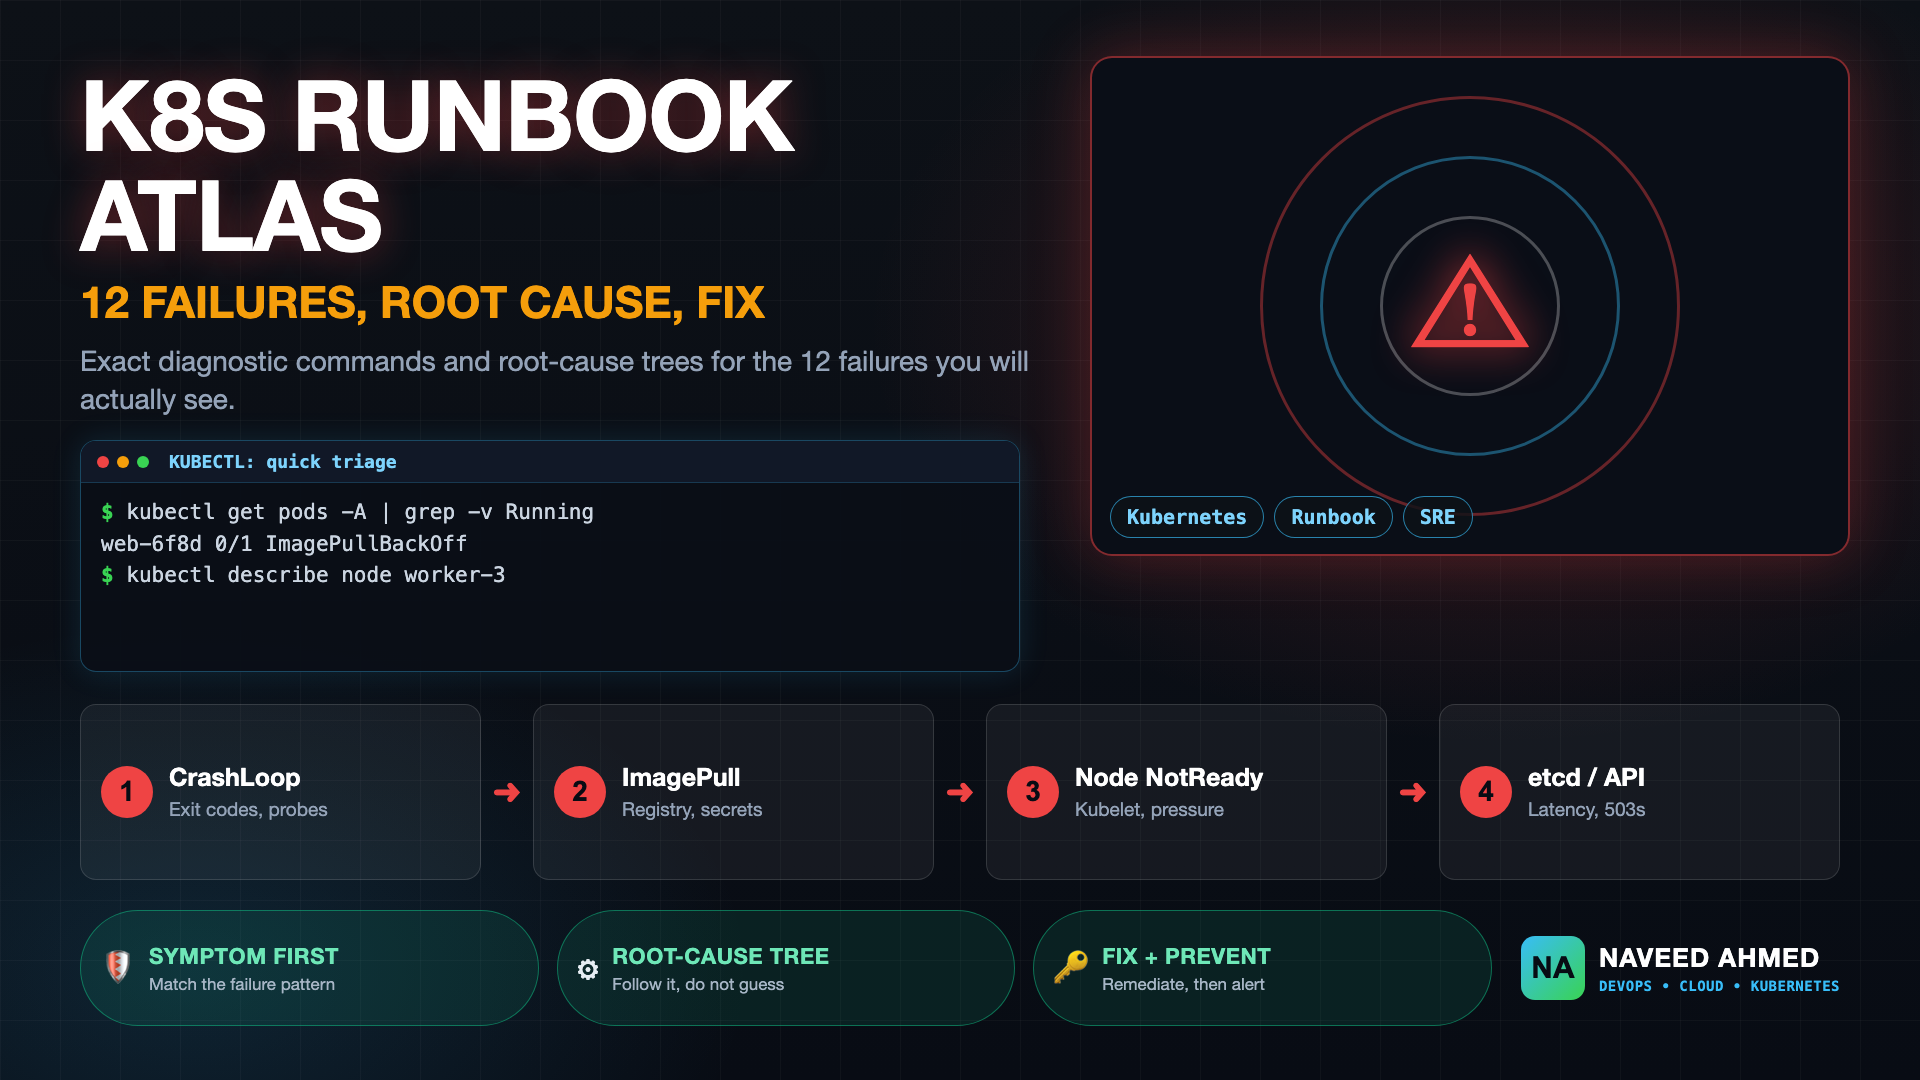
Use rolling updates with readiness probes and a conservative maxUnavailable, and alert on restart counts, not only on pod phase. A bad release should stall at the first replica instead of taking the service down. These habits are the surest way to stop Kubernetes CrashLoopBackOff from becoming a recurring incident. For a wider triage order see the Kubernetes runbook for 12 production failures, and for hands-on drills try the kubectl practice game.
Frequently Asked Questions
What does CrashLoopBackOff mean in Kubernetes?
It means a container starts, crashes and is restarted repeatedly, and the kubelet is applying an exponential back-off delay (capped at five minutes) between attempts. The status describes the pattern, not the cause.
How do you fix Kubernetes CrashLoopBackOff?
Read the exit code with kubectl describe pod, check the previous container's logs with kubectl logs --previous, review events and probe failures, then fix the cause: memory limits, configuration, a failing dependency or a bad image or entrypoint.
Why are the logs empty for a CrashLoopBackOff pod?
The current container may have only just restarted, so ask for the previous instance with --previous. Also check init containers, and remember that a process that fails before it writes any output leaves nothing to read.
What does exit code 137 mean in CrashLoopBackOff?
It is SIGKILL (128 plus 9). It is often an OOMKill, which kubectl describe pod shows as Reason: OOMKilled, but it can also come from a failed graceful shutdown or the node killing the process under memory pressure.
How long does CrashLoopBackOff last?
Until the cause is fixed. The restart delay grows up to five minutes and resets after the container runs successfully for a while. For a broader incident checklist see Kubernetes production issues.
Further Learning & Recommended Resources
- Kubernetes Mastery Path: 24 hands-on interactive modules with live quizzes and local Minikube sandboxes.
- DevOps & SRE Interview Hub: 950+ scenario-based incident runbooks with candidate storytelling elevator pitches.
- Architecture Runbook: How to master Kubernetes step by step.