AWS Zero Downtime Migration: Architecture, Cutover and Rollback Playbook
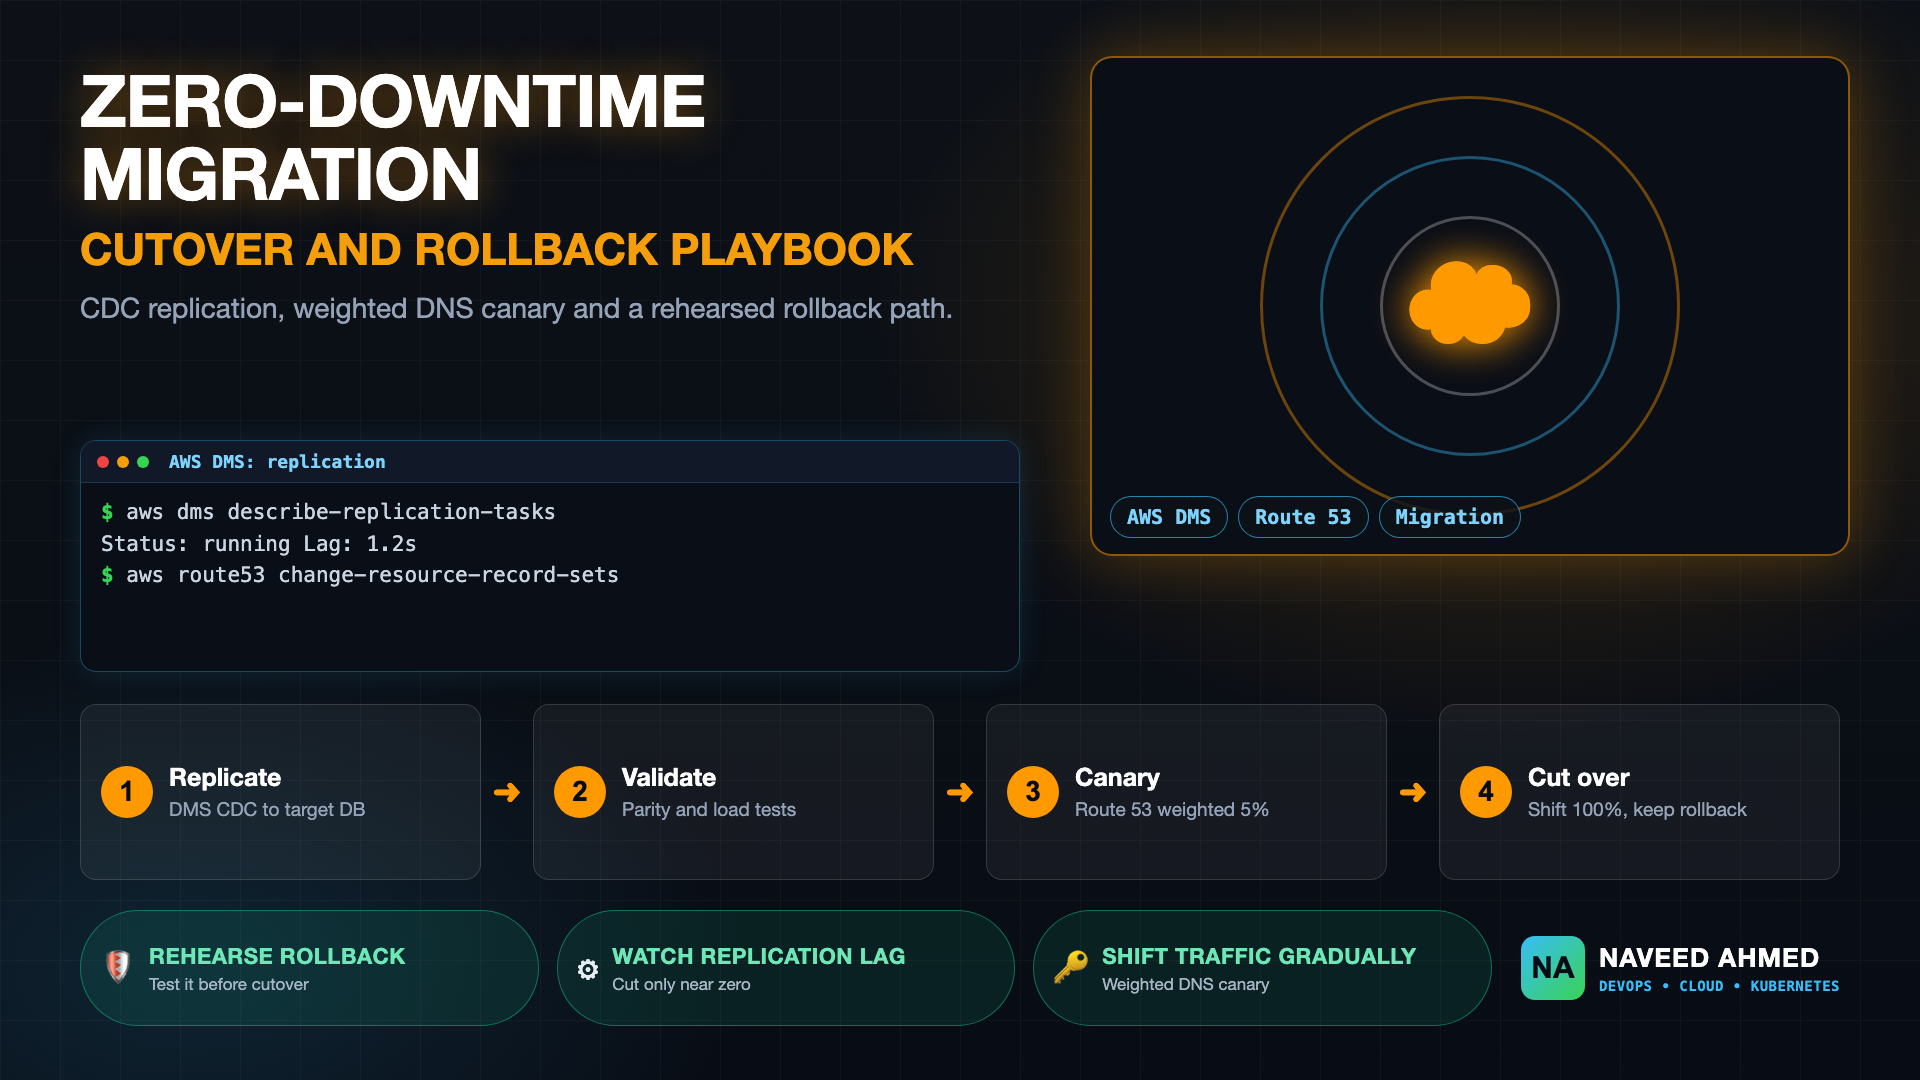
The 5-Phase AWS Zero Downtime Migration Architecture
In high-throughput environments processing thousands of transactions per second, "scheduled maintenance windows" are commercially unacceptable. A true zero-downtime migration requires running legacy and AWS environments in parallel, establishing real-time bi-directional or continuous replication, and executing a controlled canary cutover.
Phase 1: Network Foundation & Target VPC Provisioning
Before any data moves, establish a dedicated high-throughput, low-latency hybrid network connection between your existing data center (or source cloud) and AWS using AWS Direct Connect or redundant IPsec AWS Site-to-Site VPN tunnels with Transit Gateway.
# Test IPsec MTU and throughput before provisioning DMS replication instances
ping -M do -s 1422 <AWS_TRANSIT_GATEWAY_PRIVATE_IP>
iperf3 -c <AWS_TARGET_INSTANCE_IP> -P 8 -t 30
Ensure no overlapping CIDRs exist between the source private subnets and the destination AWS VPC. Provision multi-AZ subnets across at least three Availability Zones for resilience.
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
Phase 2: Continuous Data Replication with AWS DMS & CDC
Databases represent the highest-risk component of any migration. The goal is zero data loss (RPO = 0) and zero downtime (RTO < 1 min).
We configure AWS Database Migration Service (DMS) with Change Data Capture (CDC) utilizing source database transaction logs (WAL in PostgreSQL or Binary Logs in MySQL):
- Full Load + CDC: Captures baseline table data and continuously captures ongoing DML statements (INSERT, UPDATE, DELETE).
- Multi-AZ Replication Instance: Dedicated
dms.r6i.2xlargeor larger with provisioned IOPS (gp3/io2) to prevent replication bottlenecking. - Schema Conversion: Use AWS Schema Conversion Tool (SCT) beforehand to transform constraints, stored procedures, and triggers. Triggers must remain disabled on the target Aurora cluster during CDC load to avoid duplicate execution.
aws cloudwatch get-metric-data --metric-data-queries '[
  {
    "Id": "dms_lag",
    "MetricStat": {
      "Metric": {
        "Namespace": "AWS/DMS",
        "MetricName": "CDCLatencyTarget",
        "Dimensions": [{"Name": "ReplicationTaskIdentifier", "Value": "prod-db-migration-task"}]
      },
      "Period": 60,
      "Stat": "Maximum"
    }
  }
]' --start-time $(date -u -v-1H +%Y-%m-%dT%H:%M:%SZ) --end-time $(date -u +%Y-%m-%dT%H:%M:%SZ)Phase 3: Stateless Container Workloads & Shadow Testing
Containerize application workloads and deploy them onto Amazon EKS or Amazon ECS Fargate. Before sending production user traffic:
- Shadow / Mirror Traffic: Utilize Envoy / NGINX / Istio or AWS ALB traffic mirroring to clone 10-20% of incoming live read traffic to the AWS environment without returning responses to users.
- Latency & Query Profiling: Verify that Amazon Aurora PostgreSQL handles real production query concurrency with acceptable cache hit ratios and execution times.
- Circuit Breaker Verification: Test external API dependencies, Secrets Manager caching, and Redis cluster failovers.
Phase 4: The 60-Minute Cutover Window & Route 53 Canary
Execute cutover following this strict step-by-step procedure:
| Time | Action | Verification |
|---|---|---|
| T - 48 Hours | Reduce Route 53 DNS TTL to 60 seconds | dig +nocmd api.domain.com any +multiline +noall +answer |
| T - 2 Hours | Verify DMS CDC Latency is < 1 second | CloudWatch CDCLatencyTarget < 1000ms |
| T - 30 Min | Deploy read-write application pods to Amazon EKS | Pods Ready kubectl get pods -n prod -l app=api |
| T - 15 Min | Shift 10% traffic to AWS ALB via Route 53 Weighted Record | Monitor HTTP 5xx & p99 latency in Datadog/CloudWatch |
| T - 0 Min | Shift 100% traffic to AWS ALB; freeze legacy writes | Verify zero writes to legacy source DB |
| T + 15 Min | Enable reverse DMS task (AWS Aurora → Legacy DB) | Enables instant rollback without data loss if needed |
Phase 5: The Instant Rollback Playbook
A migration without a verified rollback plan is an unacceptable operational risk. By setting up reverse CDC replication (streaming from AWS Aurora back to the on-prem database immediately after cutover), the legacy environment remains a fully synchronized live replica.
If an unrecoverable defect occurs within the first 24 hours:
# 1. Flip Route 53 weighted record back to legacy endpoint (instant 60s propagation)
aws route53 change-resource-record-sets --hosted-zone-id Z1234567890   --change-batch '{"Changes":[{"Action":"UPSERT","ResourceRecordSet":{"Name":"api.domain.com","Type":"A","SetIdentifier":"AWS","Weight":0,"TTL":60,"ResourceRecords":[{"Value":"198.51.100.10"}]}}]}'

# 2. Confirm traffic returns to legacy cluster with zero lost transactions
Have questions about this architecture or scaling your infrastructure?
Whether you're planning a complex cloud migration, optimizing Kubernetes reliability, or designing autonomous AI workflows, I'm always open to discussing architecture and technical challenges with engineering teams.
Connect with Naveed on LinkedIn →Go/No-Go Criteria Before an AWS Zero Downtime Migration Cutover
The cutover window should be boring. The decision to start it should be made earlier, against criteria you wrote down in advance, so nobody is negotiating under pressure. Before any traffic moves, confirm each of the following and record who signed off.
- Replication is healthy: the DMS task is running, lag is near zero and stays there under normal load, and there are no unresolved table errors.
- Data parity is proven: row counts and checksums on critical tables match between source and target, and a sample of business queries returns identical results.
- Shadow testing is clean: mirrored traffic has run long enough to cover peak patterns, with error rates and latency inside agreed limits.
- Rollback is rehearsed: the team has practised the rollback end to end, including how replication is reversed so no writes are lost.
- Capacity is ready: the target environment has been load tested at expected peak, with autoscaling and quotas checked.
- People and communication are set: owners are named for each step, the freeze window is announced and stakeholders know the abort criteria.
If any item is red, the answer is no-go and you reschedule. After the migration, run a structured review of the new environment with an infrastructure audit checklist, and look for savings with the guide to reduce AWS costs. If you are codifying the target network and accounts, the Terraform AWS architecture shows a layout that scales.
Frequently Asked Questions
How do you achieve zero downtime during database migration to AWS?
Zero downtime database migrations are achieved using AWS Database Migration Service (DMS) with Continuous Data Capture (CDC) enabled alongside an initial full load. The source database continues servicing live production traffic while DMS continuously streams transaction logs into Amazon Aurora. Once replication lag drops under 1 second, a brief maintenance window or dual-write application layer synchronizes final sequences before cutover.
What is the safest cutover strategy for DNS traffic shifting?
The safest cutover strategy uses Amazon Route 53 weighted routing records with a reduced TTL (60 seconds) configured 48 hours in advance. Traffic is shifted gradually (e.g., 5% -> 25% -> 50% -> 100%) while automated health checks and CloudWatch anomaly monitors track error rates and p99 latency.
What triggers an immediate migration rollback?
An immediate rollback is triggered if: 1) DMS CDC replication lag exceeds 5 minutes during pre-cutover, 2) HTTP 5xx error rate exceeds 0.5% during canary routing, 3) p99 latency degrades by more than 200%, or 4) data validation checksums fail between source and target.