AI Agents for DevOps: How to Automate Runbooks Safely with MCP
The 3-Tier Autonomous Ops Architecture
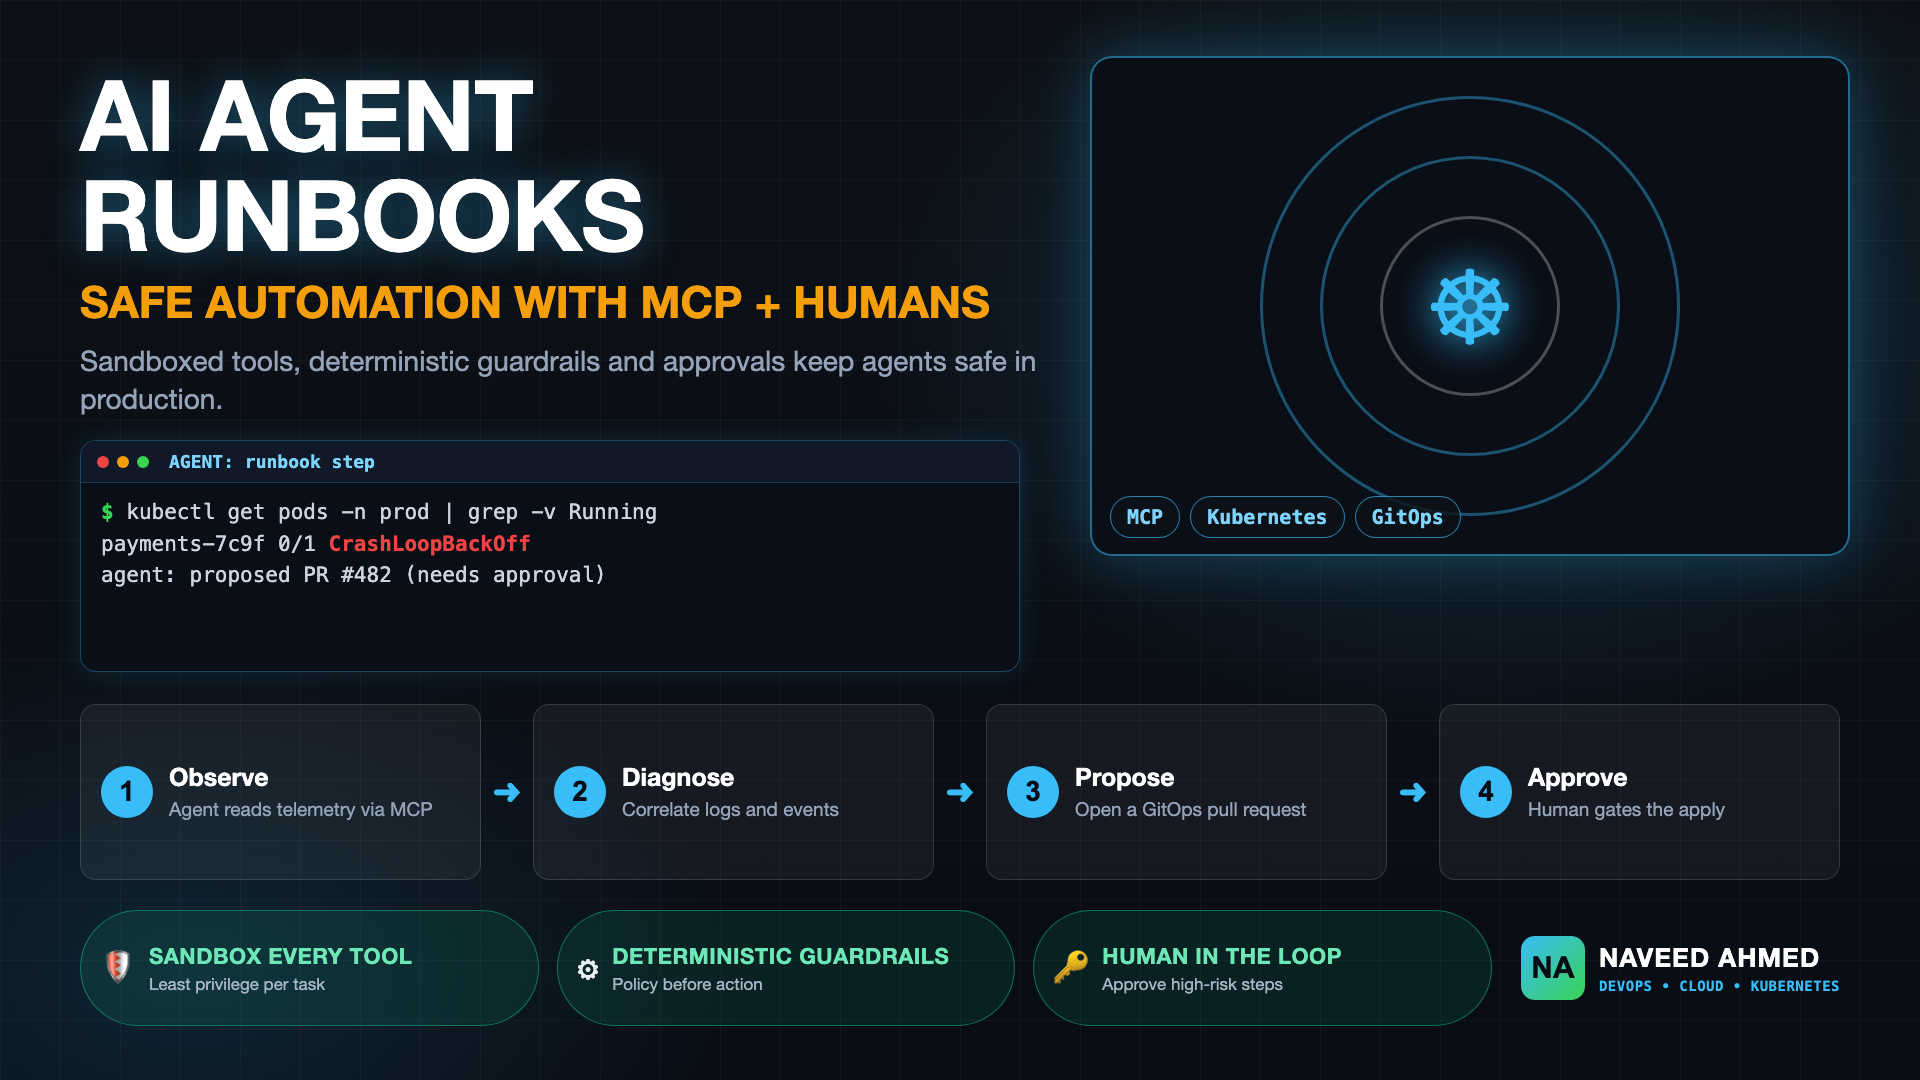
AI agents for DevOps must never be a monolithic LLM prompt. Production-grade systems decouple the agent into three strictly governed tiers:
- Perception Tier (MCP & Telemetry): Receives webhooks from PagerDuty/Datadog and fetches diagnostic context using strictly defined Model Context Protocol (MCP) read-only tools.
- Reasoning & Plan Generation (LLM Core): Analyzes telemetry against runbook specifications, formulates a hypothesis, and generates a structured, deterministic remediation plan.
- Execution & Guardrails Tier (Deterministic Sandbox): Validates the plan against security policies, enforces Human-in-the-Loop (HITL) gates, and executes idempotent scripts with automated rollback verification.
Standardizing Tool Use with Model Context Protocol (MCP)
Instead of giving the LLM unrestricted bash or ssh access, expose purpose-built MCP servers. Every tool call is strongly typed, logged, and audited.
// Example MCP Tool Definition for Kubernetes Diagnostics
{
  "name": "k8s_get_pod_diagnostics",
  "description": "Retrieves recent pod logs, exit codes, and event history for a failing pod",
  "parameters": {
    "type": "object",
    "properties": {
      "namespace": {"type": "string", "description": "Kubernetes namespace"},
      "pod_name": {"type": "string", "description": "Pod name"}
    },
    "required": ["namespace", "pod_name"]
  }
}The 3-Tier Action Classification Matrix
| Tier | Classification | Examples | Execution Policy |
|---|---|---|---|
| Tier 0 | Read-Only Diagnostics | kubectl logs, CloudWatch metric queries, tracing |
Fully Autonomous (Instant) |
| Tier 1 | Non-Destructive Remediations | Restarting stateless pod, flushing Redis cache, scaling replicas | Autonomous with Threshold Guards |
| Tier 2 | Destructive / Stateful Operations | Node drain, database failover, DNS routing shift, schema migrate | Mandatory Human Approval (HITL) |
Slack-Based Approval Gateways
When an AI agent determines that a Tier 2 action is required to resolve an incident:
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
- The agent pauses execution and posts an interactive card to the
#sre-incidentsSlack channel detailing: Root Cause Hypothesis, Proposed Action, Expected Impact, and Rollback Command. - An authorized on-call engineer reviews the diff and clicks Approve.
- The Slack webhook transmits an authenticated cryptographic callback to the agent, which executes the remediation and reports verification metrics.
{
  "incident_id": "INC-84920",
  "agent": "MORPHEUS-v2",
  "action": "scale_deployment",
  "target": "checkout-service",
  "approved_by": "naveed@naveedkumbhar.com",
  "pre_check_latency_p99": "1420ms",
  "post_check_latency_p99": "180ms",
  "status": "RESOLVED_SUCCESSFULLY"
}
Have questions about this architecture or scaling your infrastructure?
Whether you're planning a complex cloud migration, optimizing Kubernetes reliability, or designing autonomous AI workflows, I'm always open to discussing architecture and technical challenges with engineering teams.
Connect with Naveed on LinkedIn →Rolling Out AI Agents for DevOps in Phases
The safest way to adopt AI agents for DevOps is to widen their authority in stages, and to advance only when the evidence from the previous stage supports it.
Phase 1: Read-only observation
Give the agent read-only tools: query logs, list pods, read dashboards. It can summarize an incident and propose a likely cause, but it cannot change anything. Compare its summaries with what your on-call engineers conclude, and track how often it is right and how often it is confidently wrong.
Phase 2: Suggest through pull requests
Let the agent open a pull request or ticket with a proposed fix instead of applying it. A human reviews and merges. This keeps every change in version control and gives you a labelled dataset of accepted and rejected proposals.
Phase 3: Supervised execution of low-risk runbooks
Allow the agent to run a short allowlist of reversible, well-understood runbooks, such as restarting a stateless deployment, after a human approves in chat. Every parameter is typed and validated, and every action supports a dry run first.
Phase 4: Limited autonomy with hard limits
Only for actions that have proven safe in phase 3 should you remove the approval step, and even then with rate limits, a blast-radius cap and an automatic stop if error rates rise. Anything unfamiliar still routes to a human, which is the same principle behind human in the loop automation.
Audit Trails and Kill Switches for AI Agents
An agent you cannot audit is an agent you cannot trust. Log every tool call with its inputs, outputs, the incident it belongs to and the person who approved it, and write those logs to storage the agent itself cannot modify. Track approval latency, rollback rate and the share of proposals engineers reject, because those numbers show whether the agent is earning more autonomy or losing it.
Plan for the bad day as well. Keep a single kill switch, ideally a feature flag, that disables every agent action at once. Add per-tool timeouts and rate limits so a looping agent runs out of budget instead of out of control. Treat the agent's credentials like any other production identity: least privilege, short-lived and revocable.
Common failure modes and mitigations
- Prompt injection through logs: logs and tickets are untrusted input. Never let free text choose a tool or a parameter without validation against an allowlist.
- Over-broad permissions: scope each tool to one namespace or resource type, so a mistake has a small blast radius.
- Hallucinated resources: require tools to verify that a named resource exists before acting on it.
- Stale runbooks: version runbooks next to the code and review them after every incident the agent handles.
To see where agents fit in the wider lifecycle, read what agentic SDLC means for engineering teams, and for the career angle see why AI is a DevOps ally.
Frequently Asked Questions
What is the Model Context Protocol (MCP) and why is it essential for DevOps AI agents?
The Model Context Protocol (MCP), open-sourced by Anthropic, provides an open standard for AI models to securely connect to external tools, databases, and APIs. In DevOps, MCP servers expose controlled, strictly typed interfaces to Kubernetes clusters, CloudWatch metrics, or PagerDuty APIs, replacing dangerous, unconstrained bash execution with auditable JSON-RPC tool calls.
How do you implement Human-in-the-Loop (HITL) for high-risk operations?
Human-in-the-Loop is implemented by classifying actions into risk tiers. High-risk operations (e.g. database failover, node drain, DNS modification) generate an interactive confirmation payload sent to a dedicated Slack or Teams channel via webhook. The AI agent pauses execution until an authorized engineer clicks Approve or Deny.
How do you prevent prompt injection in DevOps AI agents?
Prompt injection is prevented by separating untrusted user data (e.g. error logs, pod descriptions, customer input) from system instructions, strictly validating all tool inputs against JSON schemas, and running all execution through hardened sandboxes with read-only defaults.