Kubernetes Production Issues: 10 Problems I Check First (SRE Incident Runbook)
Walk through live Kubernetes troubleshooting scenarios with Naveed—including Exit Code 137 OOMKilled diagnostics, CoreDNS 5-second conntrack race conditions, and graceful termination races—with production CLI commands and architectural mental models.
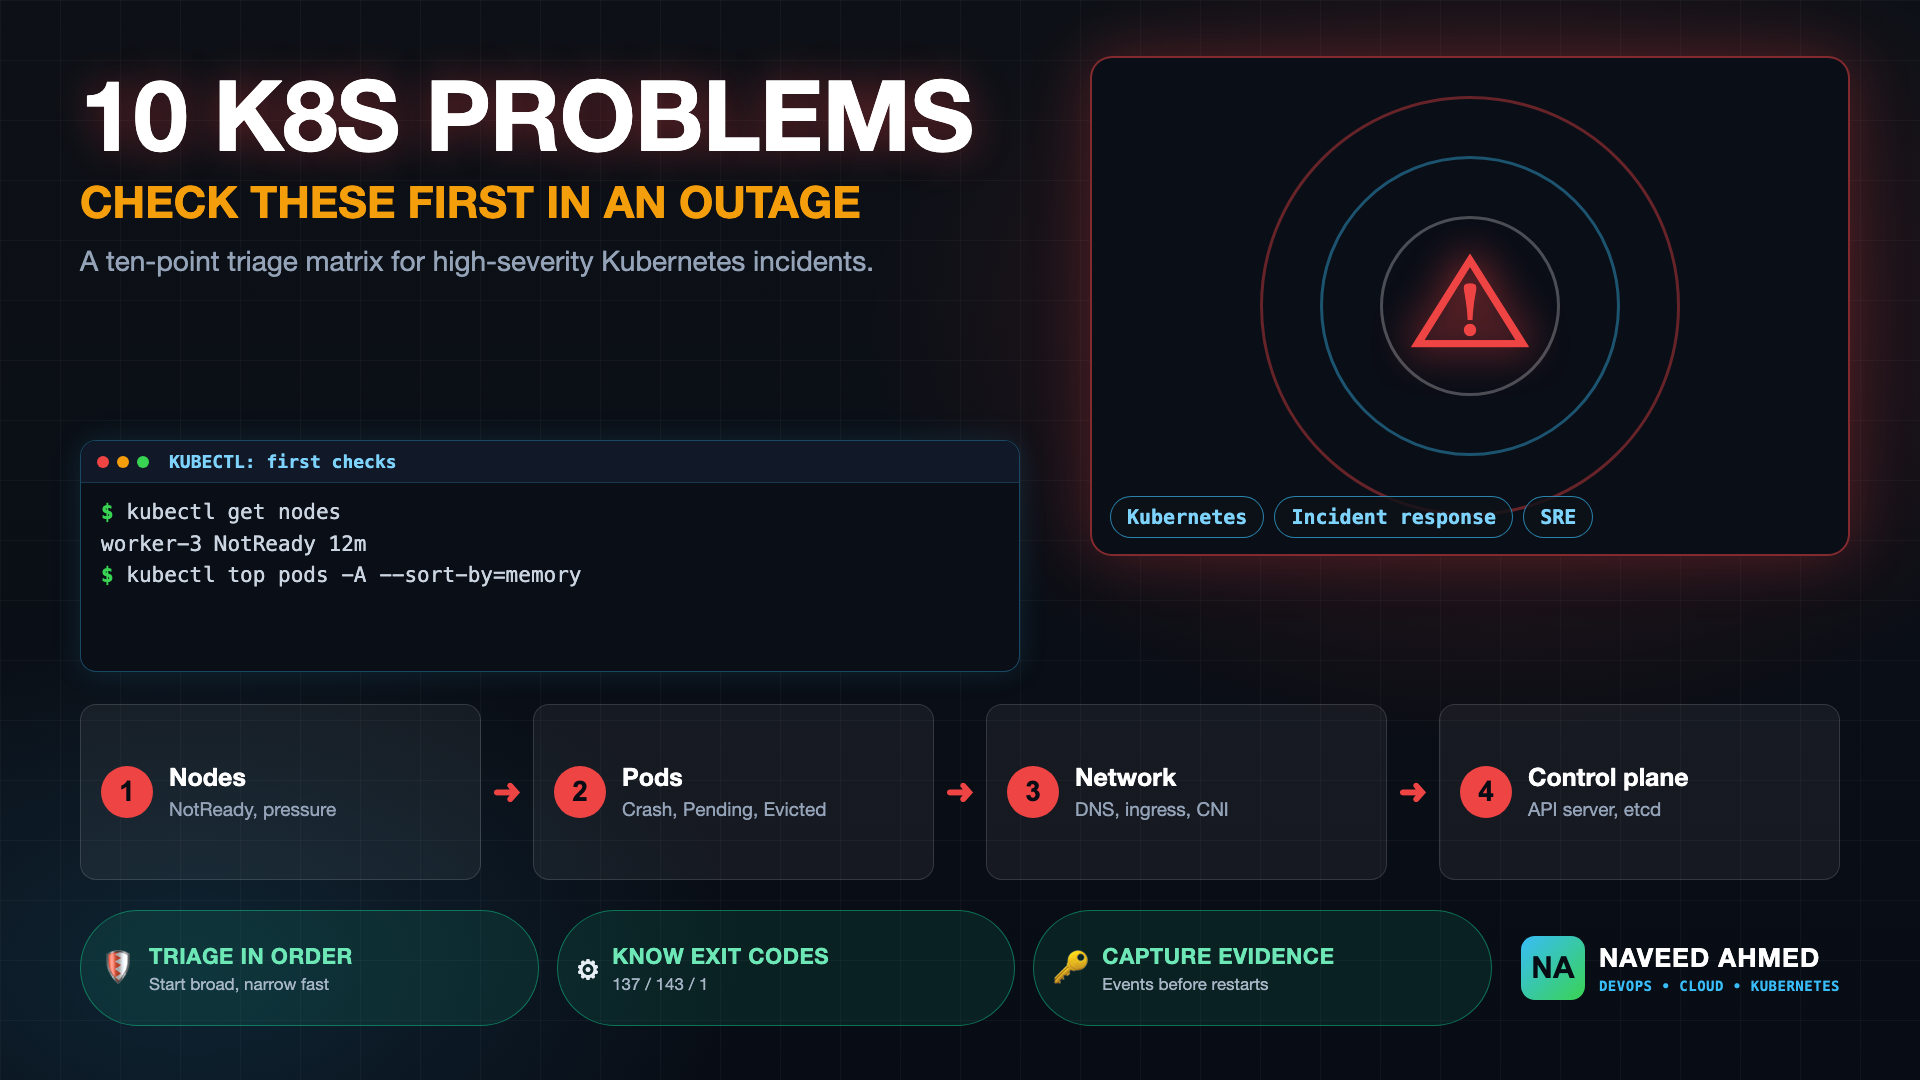
Kubernetes Production Issues: The 10-Point SRE Triage Matrix
During a production incident, triage follows a strict hierarchy: Host Node → Networking/DNS → Control Plane → Container Runtime → Application Code. Never debug application logs until you confirm the infrastructure substrate is healthy.
Exit Code 137: Linux OOMKilled vs Node Memory Pressure
Exit code 137 means SIGKILL was dispatched. The critical question: Was it a container-level OOM (exceeded resources.limits.memory) or a node-level OOM (host kernel killed processes due to node exhaustion)?
# Check if container was OOMKilled
kubectl get pods -n prod -o jsonpath='{range .items[*]}{.metadata.name}{"	"}{.status.containerStatuses[*].lastState.terminated.reason}{"	"}{.status.containerStatuses[*].lastState.terminated.exitCode}{"
"}{end}' | grep OOMKilled

# Check node dmesg for kernel kill events
kubectl debug node/<node-name> -it --image=busybox -- chroot /host dmesg -T | grep -i -E "oom[-_]killer|killed process"
The Fix: Differentiate RSS memory from Page Cache. If JVM or Node.js heap is configured higher than container memory limits, tune heap flags (-XX:MaxRAMPercentage=75.0).
The 970+ Incident Handbook & K8s Runbooks are exclusive to subscribers — unlock for FREE
Get battle-tested production runbooks, AWS architecture blueprints, and zero-downtime CI/CD post-mortems sent directly to your inbox. 100% free, no spam.
Exit Code 143: Graceful Termination Timeout Races
When a pod exits with 143, it received SIGTERM but failed to shutdown gracefully within terminationGracePeriodSeconds (default: 30s), forcing kubelet to send SIGKILL.
# Inspect pod shutdown duration events
kubectl get events -n prod --field-selector reason=Killing --sort-by='.metadata.creationTimestamp'
The Fix: Implement a preStop hook with a sleep (e.g. sleep 10) to allow Kubernetes endpoints and kube-proxy iptables to remove the pod IP before the application stops accepting traffic, and increase terminationGracePeriodSeconds: 60.
Liveness Probe Cascading Death Spirals
The most destructive configuration mistake in Kubernetes: configuring a liveness probe to check downstream dependencies (PostgreSQL database or Redis). If the database slows down, all pods fail their liveness probe simultaneously, kubelet restarts all containers in a stampede, destroying connection pools and taking down the entire system.
The Rule: Liveness probes must only verify if the container process is deadlocked internally (shallow /healthz check returning HTTP 200). Use readiness probes for dependency checks so traffic is temporarily detached without restarting the process.
CoreDNS 5-Second Latency & Conntrack Table Collisions
When external or inter-pod requests experience sudden 5.00-second latency spikes, it is almost always the Linux netfilter conntrack UDP race condition between IPv4 (A) and IPv6 (AAAA) DNS queries.
# Check conntrack insertion drops
sudo conntrack -S

# Verify CoreDNS response metrics
kubectl top pods -n kube-system -l k8s-app=kube-dns
The Fix: Deploy NodeLocal DNSCache daemonset on every node to serve DNS over local TCP loops, eliminating conntrack UDP races entirely.
AWS VPC CNI IP Address Exhaustion
Pods remain stuck in ContainerCreating or FailedCreatePodSandBox with error: "failed to assign an IP address to container".
# Check aws-node daemonset IP pool status
kubectl get pods -n kube-system -l k8s-app=aws-node
kubectl describe daemonset aws-node -n kube-system | grep -A 8 "Environment:"
The Fix: Enable Prefix Delegation on the AWS VPC CNI. Set ENABLE_PREFIX_DELEGATION=true and configure WARM_PREFIX_TARGET=1, expanding node IP capacity from ~30 IPs to over 250 IPs per instance.
Remaining Essential Checks
- 6. Node NotReady from Inode Exhaustion: Check
df -ih. Millions of orphaned container logs or build cache artifacts fill the inode table even when disk space is mostly free. - 7. etcd Fsync Latency Spikes (> 10ms): High disk IOPS on control plane nodes causes etcd leader election loss. Ensure etcd storage uses dedicated io2/gp3 volumes with guaranteed IOPS.
- 8. Ingress 502 Bad Gateway (Keep-Alive Mismatch): Occurs when the AWS ALB idle timeout (60s) is longer than the application server keep-alive timeout (5s in Node.js). Set upstream keep-alive to 65s.
- 9. ImagePullBackOff (Docker Hub / ECR Rate Limits): Verify IAM role permissions for ECR and deploy pull-through caches to prevent public registry rate throttling.
- 10. Karpenter Node Provisioning Failures: Check
kubectl logs -n karpenter -l app.kubernetes.io/name=karpenterforInsufficientInstanceCapacityor missing subnet tags.
Have questions about this architecture or scaling your infrastructure?
Whether you're planning a complex cloud migration, optimizing Kubernetes reliability, or designing autonomous AI workflows, I'm always open to discussing architecture and technical challenges with engineering teams.
Connect with Naveed on LinkedIn →How to Use This Triage Order During an Incident
A checklist only helps if the team follows it under pressure. When you are working Kubernetes production issues live, agree on three things before touching a command: who is incident commander, what the customer impact is, and whether a recent change is the likely trigger. If a deploy went out shortly before the alert, rolling it back is usually faster and safer than debugging forward.
Then work the matrix from the top, writing down what you checked and what you saw. Capture evidence such as events, previous container logs and node conditions before restarting anything, because a restart can erase the clue you need. When one item explains the symptoms, stop and fix that item instead of continuing down the list.
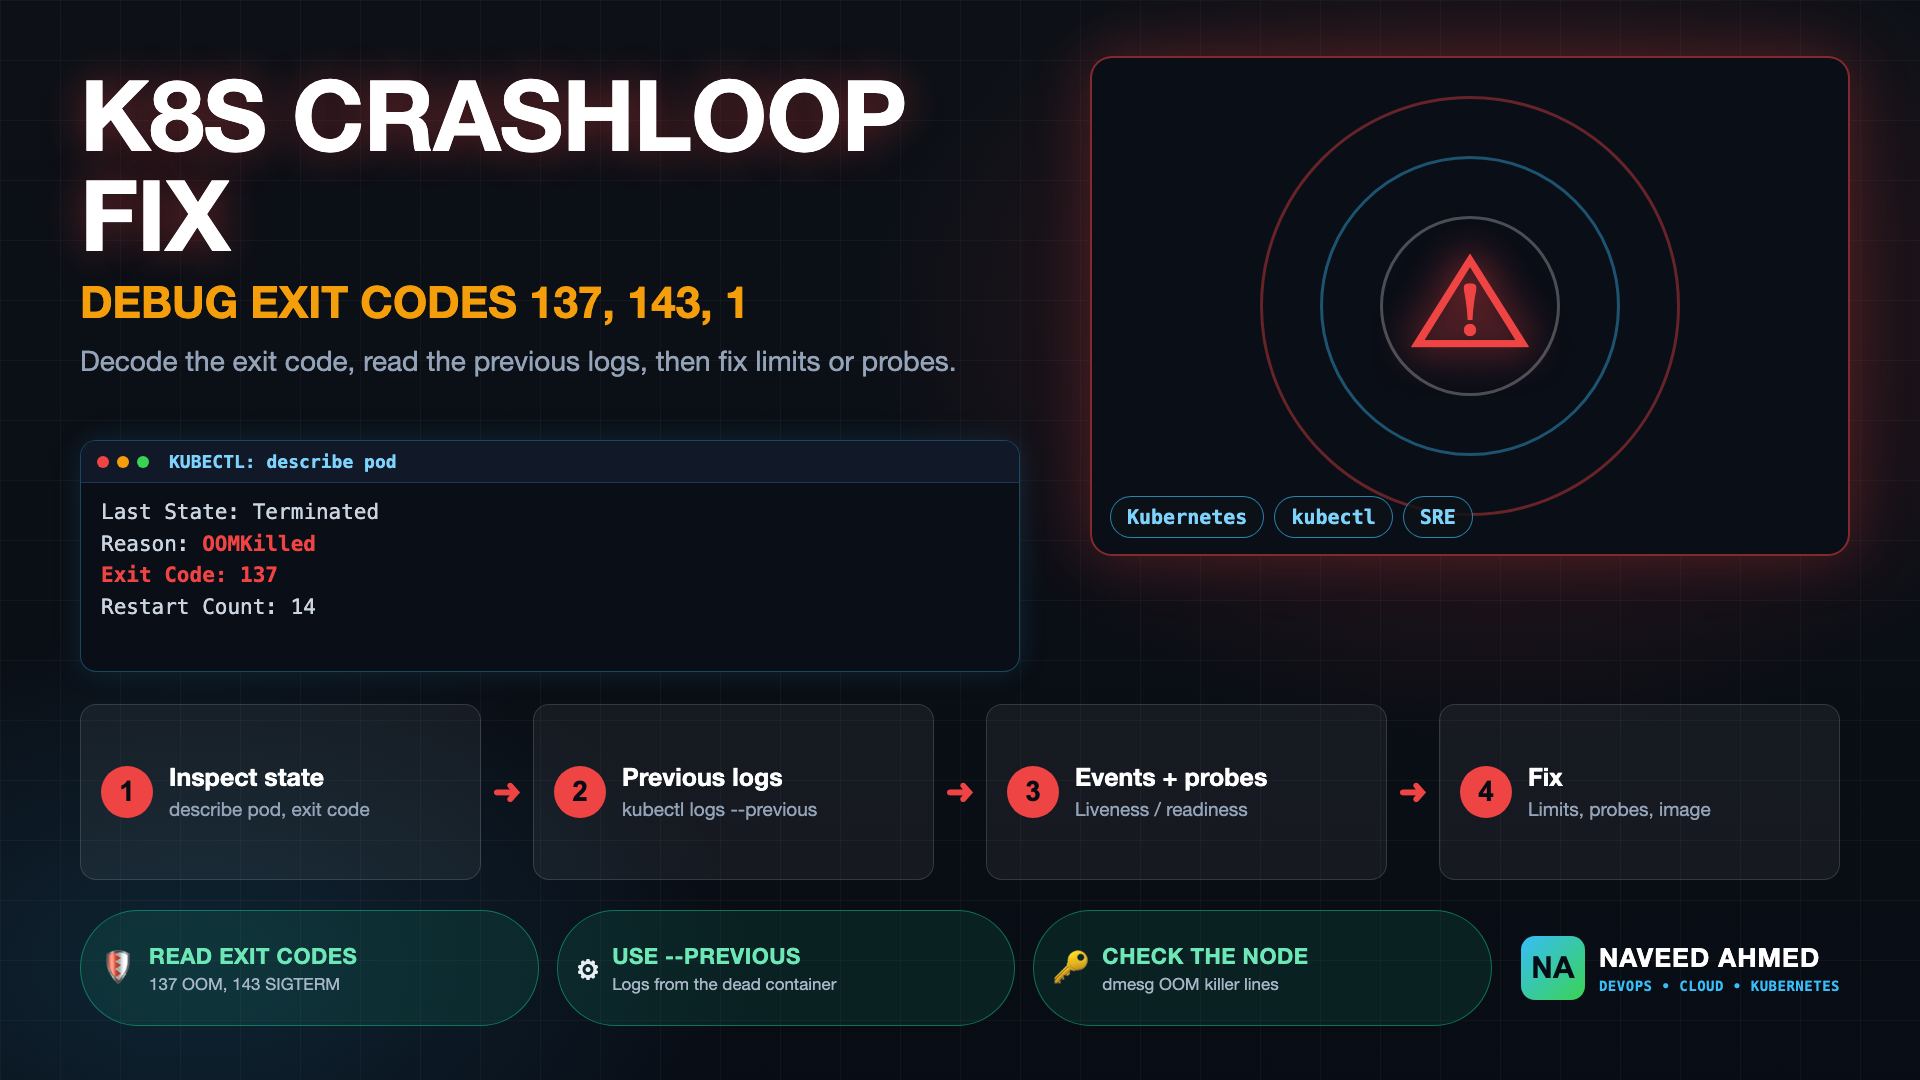
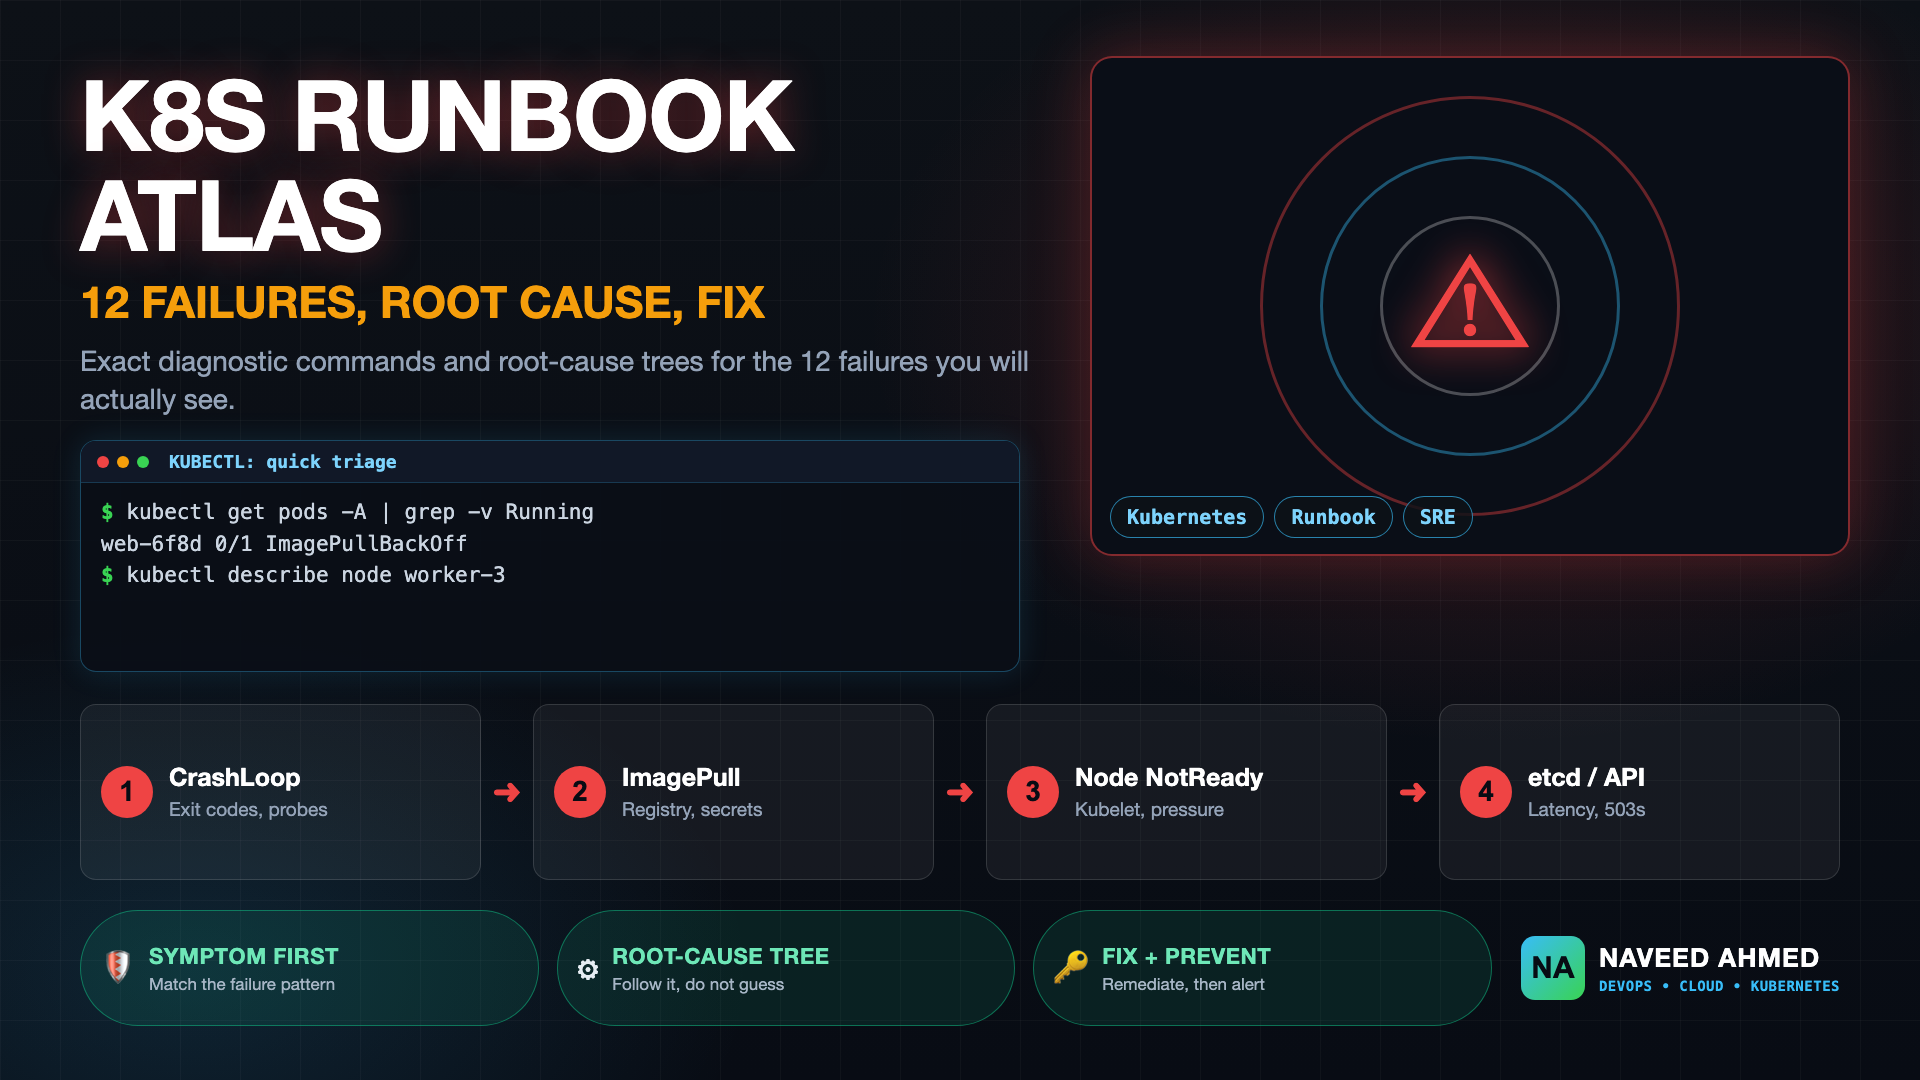
For a deep dive on the most common crash pattern, read the guide to Kubernetes CrashLoopBackOff. For the full set of failure scenarios with commands, use the Kubernetes runbook, and rehearse the whole sequence in the kubectl practice game.
Frequently Asked Questions
What is the difference between exit code 137 and exit code 143 in Kubernetes?
Exit code 137 indicates the container was killed by SIGKILL (signal 9 + 128 = 137), almost always triggered by the Linux kernel Out-Of-Memory (OOM) killer when container memory exceeds limits. Exit code 143 indicates SIGTERM (signal 15 + 128 = 143), meaning Kubernetes gracefully requested termination (e.g. node drain, rolling update, or failing liveness probe) but the app did not exit before terminationGracePeriodSeconds expired.
Why does CoreDNS cause 5-second DNS delays in Kubernetes?
The notorious 5-second DNS delay is caused by a race condition in Linux netfilter conntrack during simultaneous UDP lookups (A and AAAA records) over the same source port. This causes conntrack insert collisions and packet drops. The fix is deploying NodeLocal DNSCache or setting single-request-reopen in the pod dnsConfig.
How do you resolve AWS VPC CNI IP exhaustion?
AWS VPC CNI IP exhaustion happens when pod churn exhausts the available secondary IPv4 addresses on worker node ENIs. Resolve it by configuring WARM_IP_TARGET and MINIMUM_IP_TARGET in the aws-node daemonset, or enabling prefix delegation (ENABLE_PREFIX_DELEGATION=true) which allocates /28 IPv4 prefixes (16 IPs per slot) instead of individual IPs.